


Income
Investing
By leveraging a multi-asset class approach, our advisors aim to generate consistent monthly income from your retirement savings.

Portfolio
Management
Through portfolio monitoring, rebalancing, and strategic adjustments based on our research, your advisor will work to keep you remain aligned with your investment objectives and goals.

401(k)
Advisement
By assessing your risk tolerance, investment goals, and time horizon, our team will recommend appropriate asset allocation strategies to optimize long-term 401(k) returns.

Retirement
Planning
With Capital, you have a partner focused on all facets of your financial life to help prepare for a financially secure, happy retirement.

Financial
Planning
After a thorough assessment of your retirement, including but not limited to tax optimization and estate planning, your advisor will develop a personalized plan targeting your short and long-term financial goals.

Private
Investments
We help investors build out their private investment portfolios through exclusive access to private equity, private real estate and private credit opportunities.

Build and Preserve Your Wealth
Our comprehensive wealth management strategies aim to help you enhance and preserve your assets for a comfortable retirement and lasting wealth.

Legacy Planning and Protection
We help ensure your legacy secures the futures of your loved ones with forward-thinking estate planning.

Clarity and Confidence in Your Finances
Get a transparent roadmap for your finances, equipping you with knowledge and confidence to make smart financial choices.

Empower Your Financial Decisions
Your advisor will cut through the financial jargon to empower your control over the planning process.

Adaptive Financial Planning
Stay ahead of life’s curveballs with a flexible financial plan that evolves with your changing needs and goals.


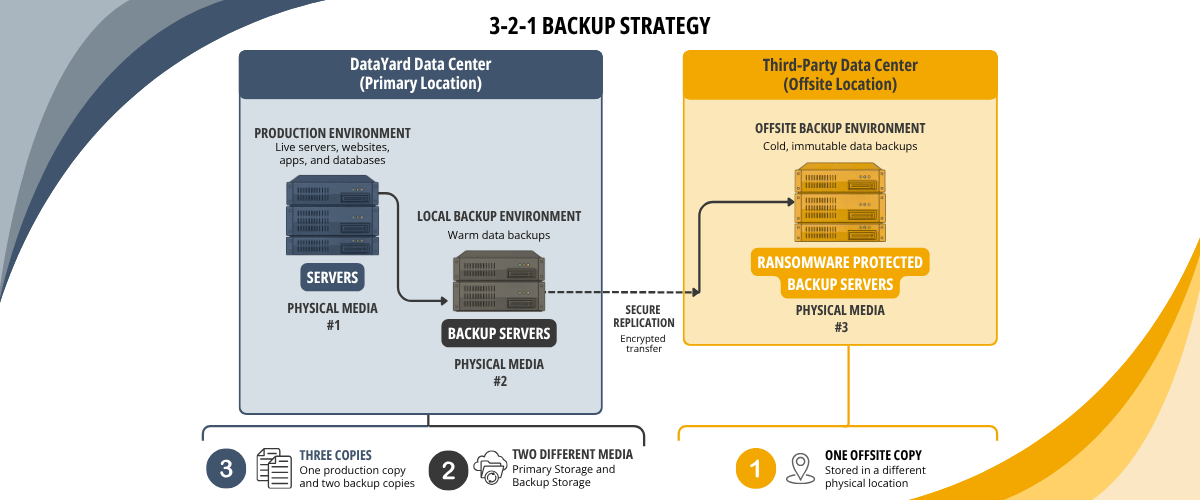
What Is the 3-2-1 Backup Strategy?
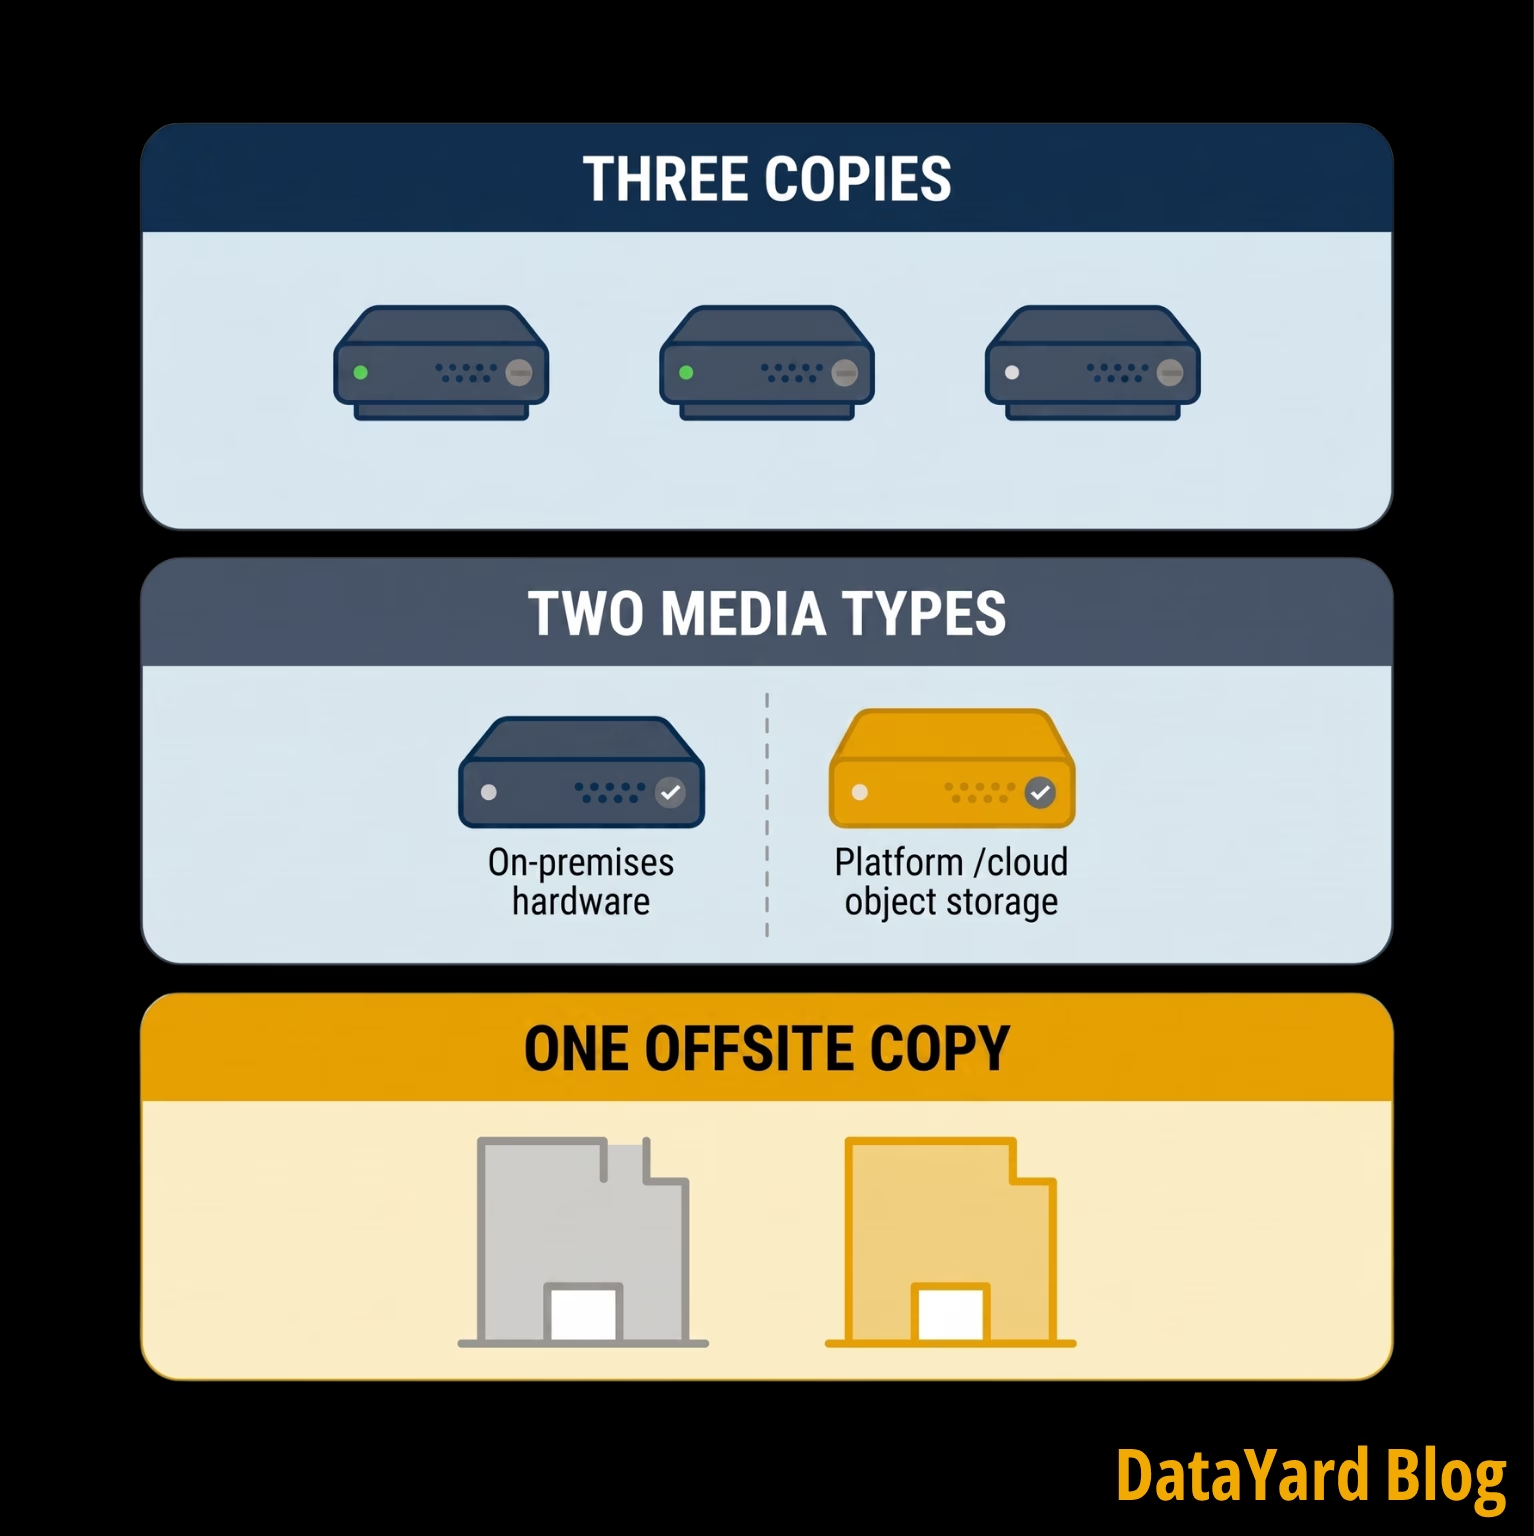
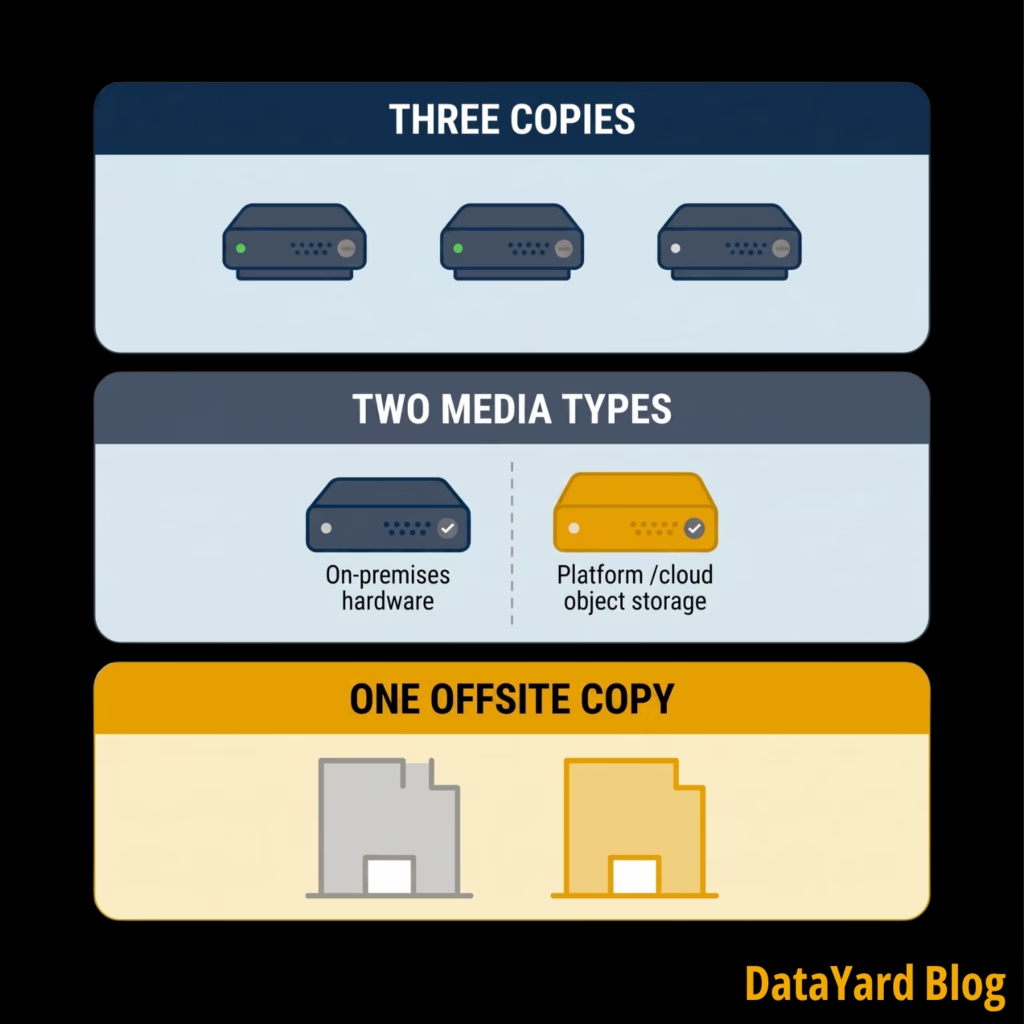
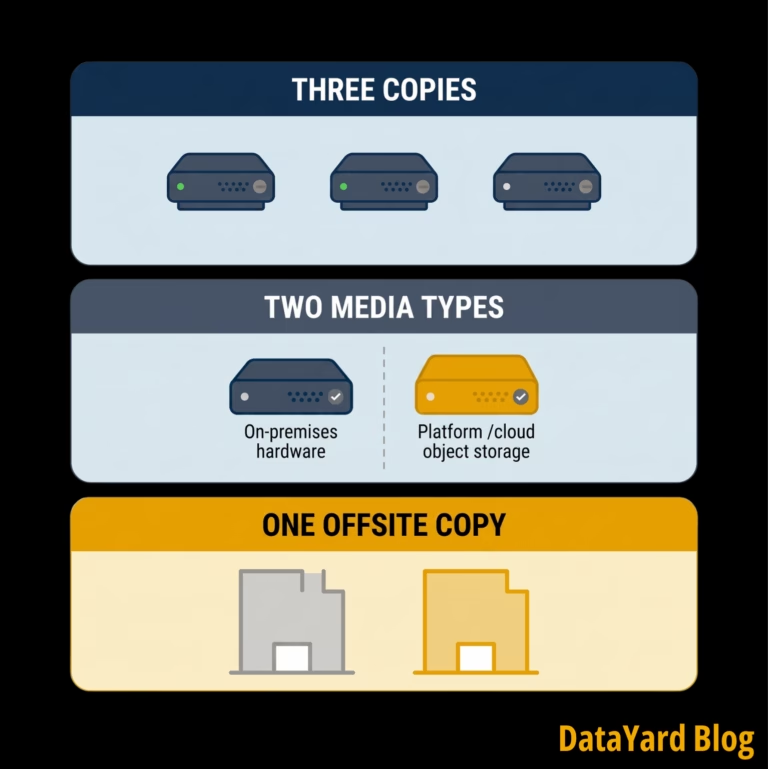
The 3-2-1 backup strategy is a data protection best-practices guideline built around three requirements:
- Three copies of your data. Your production data plus at least two backup copies. The original counts as one of the three.
- On two different types of media. Store copies across distinct storage types, such as physically-and-logically-separated on-prem server hardware and cloud object storage. If one storage system fails, it shouldn't take every copy with it.
- One copy offsite. Keep at least one copy in a separate physical location (i.e. two data centers, two offices, etc), so an incident at your primary site is less likely to reach every available copy.
The rule is generally credited to photographer Peter Krogh, who described the approach in his book on digital asset management, The DAM Book. It came out of a different technology era, but it was never tied to a product or platform. That's why it has survived the move from tape to disk to NAS to private and public cloud.
Why the 3-2-1 Backup Strategy Still Holds Up
Each part of the strategy addresses a different source of risk.
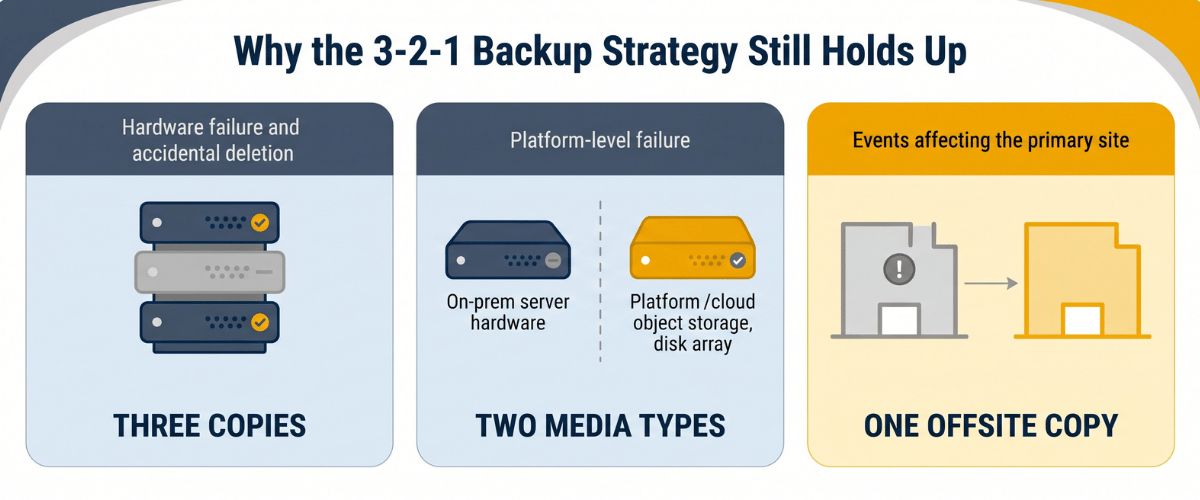
- Hardware failure and accidental deletion. Multiple copies give you somewhere to recover from when production data is corrupted or deleted. A drive fails, and two copies remain.
- Platform-level failure. Different storage media add separation. A firmware issue affecting one platform typically doesn't reach a copy held on another. A drive failure on one server cluster won't take down a physically-separated, second set of servers.
- Events affecting the primary site. An offsite copy protects your recovery data from a fire, a flood, or an extended power outage where production runs.
When used together, these three requirements reduce the odds that one infrastructure problem takes out every copy at once.
The strategy is also vendor neutral, which is less common than it sounds in this category. You can apply the principles across on-premises infrastructure, private cloud, public cloud, and hybrid environments without committing to a platform. The approach has also appeared in federal backup guidance, including a Carnegie Mellon publication on data backup options produced for US-CERT.
Where the 3-2-1 Backup Strategy Breaks Down
The strategy can break down when the environment drifts away from the documentation over time. Because of that, there are several configurations that are worth checking.
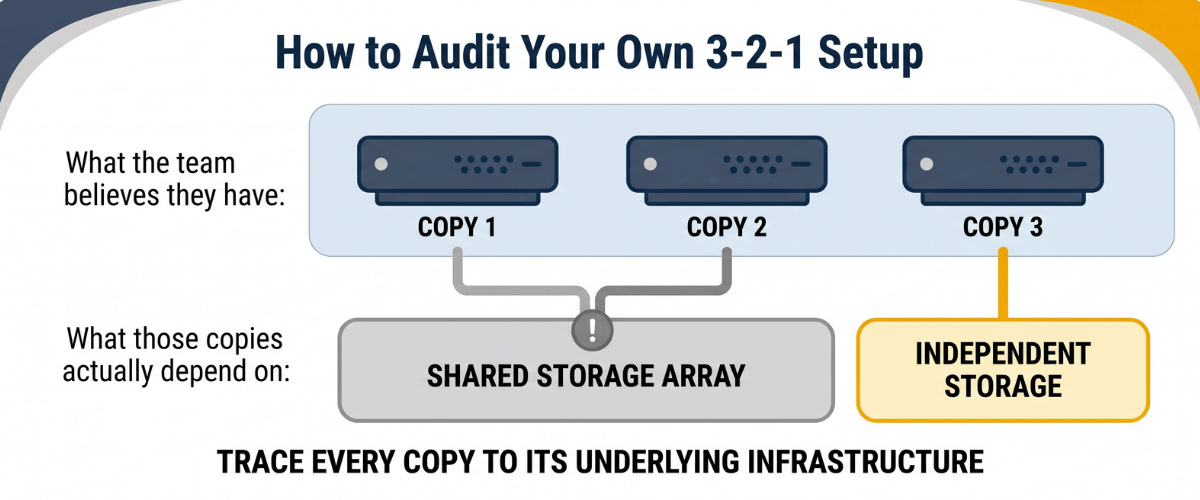
- Three copies sharing the same underlying hardware. A production VM, backup VM, and snapshot repository can look like three distinct copies but, in reality,all three can depend on the same storage array. One problem with that shared infrastructure is that a larger hardware failure can take out multiple copies at once.
- An offsite copy without enough separation. A NAS in a different closet, a second server across the parking lot, or an external drive that goes home with someone on Fridays. Each creates some physical separation, but each often shares power, networking, or exposure to the same localized event. The point of an offsite copy is meaningful separation, not just a slightly different address.
- Replication mistaken for backup. Replication maintains another copy of a system's current state, which is useful for high-availability. The problem is that unwanted changes can propagate too. Encryption from a ransomware event, a corrupted database file, or a mass deletion -- all of these can copy over cleanly. A backup with appropriate retention lets you recover from an earlier point in time. The two strategies can complement each other, but they solve different problems.
- SaaS data without a defined backup plan. Platforms such as Microsoft 365 and Google Workspace operate on a shared responsibility model. They include their own availability, retention, and recovery capabilities, and you should know exactly what those cover. If SaaS data is important to your business, document how it's protected, how long recoverable data is retained, and what your recovery options are.
- Backups that have not been tested through recovery. A completed job confirms the backup process reported success. That's it. A restore test is what tells you that the data comes back and works as expected.
| What Teams Expect | What May Actually Exist | What to Check |
|---|---|---|
| Three independent copies | Multiple copies sharing underlying storage | Trace each copy to its underlying infrastructure |
| An offsite copy | A second copy with shared physical or network dependencies | Confirm meaningful geographic and infrastructure separation |
| A backup | A replica of the current state | Confirm point-in-time recovery is available |
| Protected SaaS data | Reliance on native platform retention | Document retention and recovery capabilities for each platform |
| Verified recoverability | Successful backup job logs without real testing | Confirm the date and results of the last restore test |
How to Audit Your Own 3-2-1 Setup
A periodic review tells you whether your environment still matches the strategy you designed.
Seven Checks
- Trace every copy to the underlying infrastructure. Don't stop at a hostname or volume label. Find out where each copy actually resides and identify shared dependencies.
- Confirm that your storage types actually provide meaningful separation. Check whether a problem affecting one storage platform could reach another copy.
- Review the separation of your offsite copy. Consider geography along with shared power, network, administrative, and infrastructure dependencies.
- Check credential separation. Determine whether the credentials that administer production can also modify or delete backup data.
- Inventory your SaaS data. List the platforms holding important business information and document their backup, retention, and recovery processes.
- Confirm data retention matches your recovery needs. Consider how far back you may need to be able to restore from, and answer the question on whether or not your current retention supports that.
- Record the date and results of your last restore test. If you can't identify a recent one, schedule it, complete it, and document the outcome.
Restore Testing: The Part Most Teams Skip
A restore test goes beyond confirming a backup job completed. It brings data back into a usable environment and verifies the recovered system, data, or application works. NIST guidance for managed service providers and their small and mid-sized business customers treats backup restore testing as a distinct practice alongside conducting and maintaining those backups.
Depending on the workload, a meaningful test may include: restoring to isolated infrastructure, starting the application, checking data integrity against an expected reference point, and measuring how long recovery takes.
The timing of that process matters. Recovery time objectives (commonly known as RTOs) should reflect what your environment can actually deliver. If the business expects a system back within two hours and a tested recovery procedure takes eleven, the test just found a planning gap. That testing period is generally a better afternoon than finding that out in the middle of a real disaster scenario.
The right cadence depends on how important the system is, how quickly the environment changes, and what your recovery requirements are. Whatever interval you choose, document both the procedure and the results.
What Changed: 3-2-1-1-0 and Other Variants
The original rule predates many of today's ransomware threats. Modern backup planning has to account for more than where backup data sits. It has to account for whether an attacker or a compromised account could modify or delete it.
That has produced extensions of the original framework. One commonly referenced approach is 3-2-1-1-0, which keeps the original three requirements while adding another protected copy, such as an immutable or air-gapped copy, plus verification intended to catch backup or recovery errors. Another variation, 4-3-2, calls for four copies across three locations, with two of them held offsite.
It's worth clarifying where these new strategies come from, as most were named and popularized by backup vendors. That doesn't make the underlying advice wrong, and immutability and restore verification are both reasonable additions. It does mean the numbering is a marketing convention rather than a standard. You're not behind just because your well-designed environment doesn't match somebody's acronym.
The more useful question is what protection sits behind the numbers. Immutability, credential separation, appropriate retention, and restore testing all strengthen a backup strategy, regardless of the label. The 3-2-1 backup strategy is still a reasonable foundation, and you can add controls from there based on your recovery requirements and risk profile.
The 3-2-1 Backup Strategy in a Hybrid Environment
Most organizations no longer run a single environment. Systems get distributed across on-premises infrastructure, private cloud, colocation, public cloud, SaaS platforms, etc.
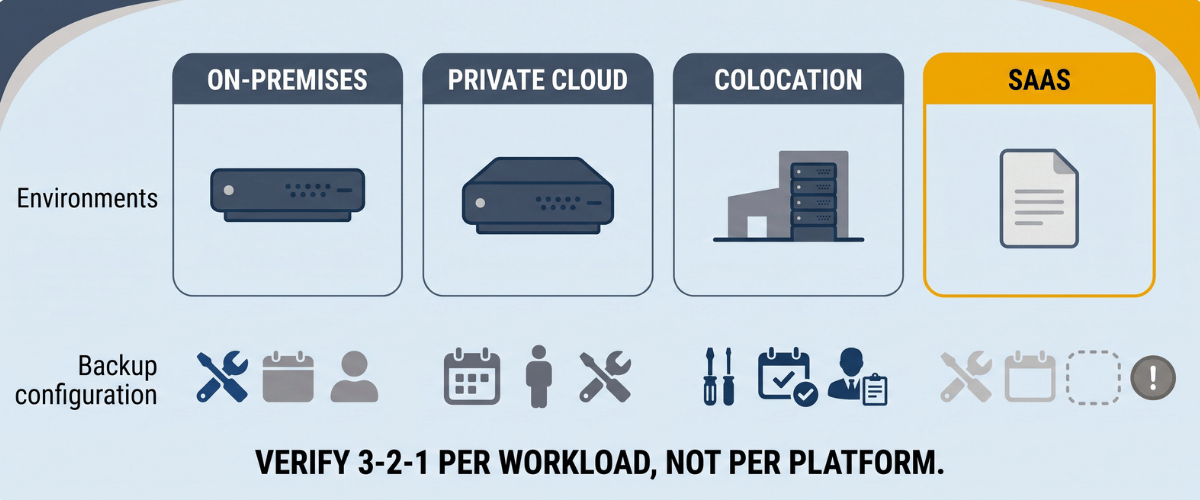
That distribution helps create geographic and infrastructure separation. but it also makes backup planning harder. Different platforms mean different tools, retention settings, administrators, and recovery processes. That's usually where a gap goes unnoticed.
Rather than treating 3-2-1 as a setting on a single backup platform, treat it as an outcome to verify for each important workload. Map the systems your business depends on. Identify where the production data and backup copies live. Document the storage and administrative dependencies behind those copies. Then confirm that the recovery options meet what your business actually requires.
If you're working through a broader infrastructure change, our cloud migration checklist for manufacturing companies blog covers how backup and recovery planning fits into a phased migration.
How DataYard Approaches Backup and Recovery
We have been supporting business infrastructure in Ohio since 1995, and we are SOC 2 Type 2 Accredited. Our approach to backup and recovery starts with understanding the systems you depend on, your recovery requirements, and what infrastructure is already in place.
Our READY backup service uses redundant backup nodes and disks, with data encrypted in flight and at rest. We can protect data from servers at your location, within DataYard's cloud or colocation environments, or at a third-party host, which means the backup architecture be designed around your environment, rather than a single deployment model.
We monitor backup jobs for successful completion and maintain recovery copies according to the agreed retention requirements. Our standard configuration includes 30 daily copies, with additional retention and recovery options available based on business needs.
DataYard can build and manage 3-2-1 backup configurations that provide multiple copies across separate storage media, including an offsite copy. That gives you a way to incorporate that best-practices framework into a managed backup environment, rather than coordinating the pieces across separate providers.
That work usually starts with our Remote Infrastructure Scalability Evaluation, where we review your current architecture against where you're trying to go before recommending anything.
Frequently Asked Questions
Is the 3-2-1 Backup Strategy Still Relevant?
Yes, it remains a useful baseline because it is technology agnostic and creates separation across copies, storage, and location. You can strengthen it further with controls such as immutable storage, credential separation, appropriate retention, and restore testing.
Can Cloud Storage Count as Both Media Types?
Possibly, although the question is how much independence exists between the copies. Two buckets in the same account with the same credentials provide less separation than two distinct platforms. Combining local and cloud-based storage is one common way to create additional separation.
Does the 3-2-1 Backup Strategy Protect Against Ransomware?
It helps, particularly through the offsite copy, but the original framework wasn't designed around modern ransomware. Common cyber attacks now target backup infrastructure directly. Immutable or otherwise protected backup copies, along with credential separation between production and backup systems, can strengthen recovery options against ransomware-related data loss.
How Often Should Backups Be Tested?
Backup testing should follow a defined schedule based on the importance of the workload, rate of change, and recovery objectives. Many environments review critical systems quarterly, and some warrant more frequent testing. The important part is performing meaningful restore tests and documenting the results.
Is Replication the Same as Backup?
No, replication maintains another version of the current system state, which means unwanted changes carry over to the replica. It supports availability rather than recovery to an earlier point in time. Backups provide retained recovery points that let you return to an earlier state. Some environments benefit from both.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
Layered security means no single control has to hold the line on its own. Three recent cybersecurity incidents show why patching is one layer, not the whole strategy.
What Layered Security Means
Layered security, often called defense in depth, means an attacker has to get past more than one layer of cybersecurity protections. Controls are built to overlap, so that a gap in one is covered by another.
Most descriptions will organize those controls by type. Physical security. The network perimeter. Endpoints. Data. Identity and access. Not to be forgotten is the human layer, which usually means training. It is a useful map of where defenses sit.
This map tells you where your defenses are. However, it does not tell you what happens when one of them fails.
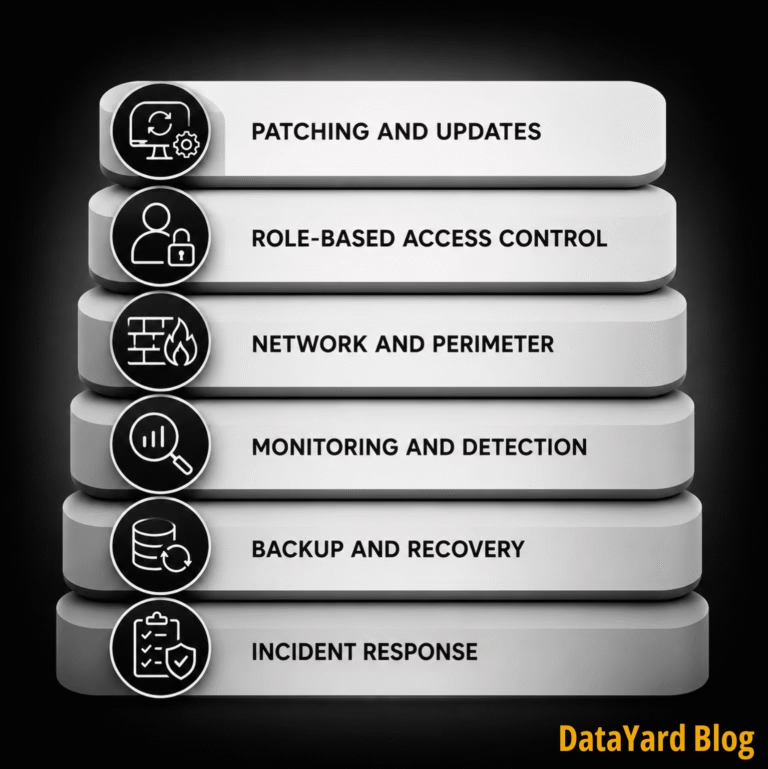
A more practical view organizes the same architecture by function, and asks a question the control-type list never gets to: what does each layer fail to cover?
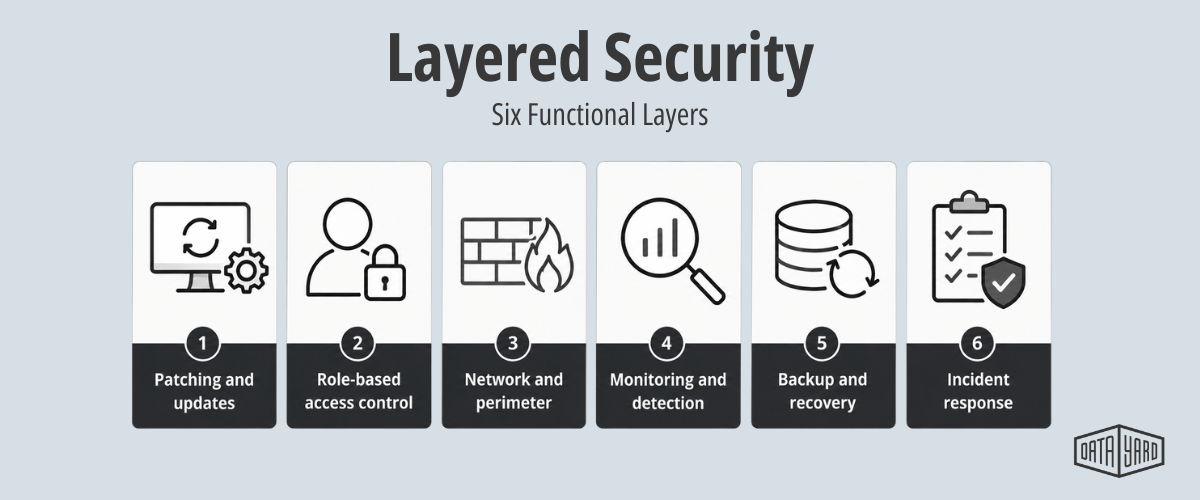
Set out that way, each of the six layers has a limit, and that limit is what the next layer is there to handle.
| Layer | What it does | What it cannot do |
|---|---|---|
| Patching and updates | Closes known vulnerabilities | Anything related to unknown or unpatched vulnerabilities |
| Role-based access control | Limits what a compromised account reaches | Prevent the compromise itself |
| Network and perimeter | Blocks and segments unwanted or malicious traffic | Stop something already inside |
| Monitoring and detection | Surfaces suspicious behavior | Prevent the behavior |
| Backup and recovery | Restores operations after an incident | Prevent the incident |
| Incident response | Determines who acts, and how fast | Work if it was never planned |
Reading the right-hand column on its own, it's clear that every line in it is the reason another layer exists.
Patching is just the first row, not the whole table.
Three incidents in just the past six weeks show what these defense layers look like when they're tested.
Three Incidents, Three Layers Under Pressure
The three incidents below happened within roughly six weeks of each other, in different industries and on different technology. What makes them worth reading side by side is that each one put a different layer under pressure, and each one exposed something the layer before it could not cover.
WordPress: When the Patching Layer Is Racing a Clock
On July 17, WordPress released version 7.0.2 to address "one critical and one high-severity security issue". Two vulnerabilities which, when chained together, could lead to remote code execution on a default installation. WordPress recommended updating immediately, then went further and enabled forced updates through the automatic update system.
If you manage WordPress sites, the immediate action is short: Check the version. Back up the site. Then update anything not already on 7.0.2, 6.9.5, or 6.8.6.
The harder part is every other patch, where nobody makes the decision for you.
We patch operating systems and platforms across the environments we manage, and the update is rarely the difficult step. The difficult step is knowing what you have in the first place. A mid-sized organization might be running dozens of applications and plugins across a mix of operating systems, endpoints, network devices, and third-party platforms. Before anyone installs anything, someone has to work out which of those are affected and judge the risk.
Then there is the step that often gets skipped under time pressure: checking whether anyone exploited the gap before you closed it. Patching closes a known path. It can't do anything about a bad actor who used that path while it was open.
N-able N-central: When the Access Layer Decides How Far It Goes
N-central is a remote monitoring and management platform. IT providers and internal IT teams use it to administer machines at scale, which means it is built to have deep access by design.
Researchers at Huntress, DataYard's managed EDR partner, reported active exploitation of a critical vulnerability in current N-central versions. Huntress reported that exploitation could hand an attacker administrative access to the N-central console, and from there reach the endpoints under its management. N-able issued hotfixes, then a revised one after the first.
The lesson is not that everyone should stop using remote management tools. Centralized administration exists because it works.
The lesson is: the tools you trust are part of your attack surface too. When one of them is compromised, the access layer decides how far the damage travels.
That makes a few questions worth answering -- before you need the answers. Which systems hold privileged access? Are they up to date? Is that access broader than the job requires? Is anyone watching how it gets used? If the tool built to administer your environment becomes the problem, what happens next?
Minnesota Water Systems: When There Is No Patch to Apply
In late July 2026, a coordinated cyberattack hit more than 30 community water systems across Minnesota. One plant went offline. Others reported communications failures or problems with automated controls. Some kept operating manually.
At the time of reporting, investigators had not publicly identified the attacker, the affected products, or the vulnerability involved.
That uncertainty is the whole lesson.
Vulnerabilities do not always arrive as an announcement with a patch attached and a convenient maintenance window to install it. Sometimes the first sign is unusual activity. Sometimes it's a system that won't respond. But by that point, the question has changed. It is no longer which update to apply. It is how fast normal operations come back, which puts the full weight of the response on a team's recovery and incident response plans.
Some of those Minnesota systems kept running manually. That is a continuity layer doing exactly what it was built for.
The same exposure applies anywhere operational technology drives the work. For example, a manufacturer whose production line depends on automated controls faces an identical question. If the controls stop responding and there is no patch to apply, what keeps running, and for how long?
Layered Security Is Also an Infrastructure Question
No single product or process would have prevented all three of these. These are different technologies, different attack paths, and different organizations.
What they share is this: in each case, the damage depended less on the vulnerability than on what the surrounding environment allowed to happen next.
That is the argument for cybersecurity layers rather than products.
The WordPress release shows where those layers meet. A WordPress update belongs to the application layer, and whoever maintains the application has to evaluate and apply it. But the application runs somewhere. That somewhere still needs its operating system patched. It needs monitoring. User access needs controlled. Backups need to exist and actually work in a restore. Network and system capacity still have to hold. If and when something breaks, someone has to work out what is happening underneath the application.
In organizations without a dedicated infrastructure or cybersecurity team, those responsibilities land on whoever is nearest, usually the IT staff or the development partner already carrying everything else. The problem is often not that a layer was intentionally ignored. It is that nobody was clearly accountable for it.
A layer nobody owns is not a secure layer.
That reality is usually a huge portion of the gap. Not whether these layers matter, but who owns each one. DataYard helps internal IT teams and development partners manage the infrastructure responsibilities behind their applications, including monitoring, environment management, security patches, backup, and recovery.
Building the Security Layers: What to Do Now
Here's a high level on how to build the six security layers. None of them require a large security budget, but all of them require someone to own them.
- Keep systems and applications current. Start with an inventory, because you can't patch what you don't know about. Take note of everything you operate, who maintains each part, and how fast a critical update goes from disclosed to deployed. Decide in advance which systems should get tested before an update and which should get patched immediately. Make sure responsibility is assigned at every layer, so critical updates do not fall between vendors.
- Control what reaches your systems. The firewall is the layer people assume is handled because it was configured once. Rules accumulate. Exceptions get added for a project and never removed. Segmentation that made sense two years ago stops matching how the network is actually used. Regularly review what is permitted, segment so that one exposed service cannot reach everything, and close anything that is open because it was easier than asking why.
- Protect privileged access. Administrative systems earn extra scrutiny because one compromised privileged account can open the door to everything behind it. Apply multi-factor authentication everywhere it can go. Limit administrative rights to only the people who need them for the work they are doing now, not the work they did two years ago. Take a periodic look at who still holds what permissions, because access can accumulate quietly. The principle is consistent: access should be enough for the job, but no broader.
- Monitor for what patching cannot prevent. A patch closes a known vulnerability. Monitoring surfaces behavior that shows up before a patch exists, before it is installed, or through a path nobody anticipated. Managed Endpoint detection, infrastructure monitoring, logging, and alerting all contribute. Alerts also need somebody reading them, which is the part that often quietly fails. The goal is not stopping every attack. It is noticing the unusual thing before it becomes an operational problem.
- Make recovery part of security. Backups get filed under maintenance. They are also a security control, and ransomware tactics have made them another target, rather than a safety net. Know what is protected, how often copies are made, and how backups are isolated from the systems they protect. Immutable backups are the strongest version of that isolation: once written, a copy cannot be altered or deleted for a set retention period, not even by someone with administrative access. Then test the restore process. A backup that has never been restored is an assumption. A tested recovery is a plan.
- Know what happens when something goes wrong. The middle of an incident is a terrible time to work out who to call. Decide in advance who owns the response, who can isolate a system, which vendors get involved, where the backups live, how critical operations continue while systems are down, and who has authority to make the call. For a smaller business, this does not need to be a hundred-page manual. One page and a phone list will do. It just needs to exist.
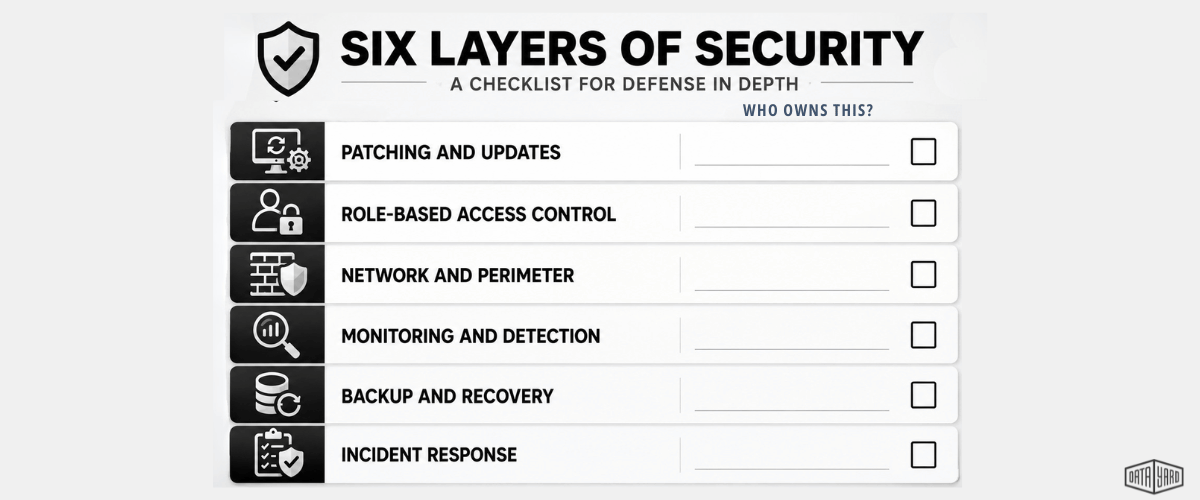
The Part That Is Harder Than the Advice
None of the above is particularly controversial. Many IT teams could write this list themselves.
The difficulty is that these are standing commitments to be reviewed regularly, not one-time tasks. Patching is continuous. Firewall rules drift. Access accumulates. Alerts need attention the day they come in.
For smaller IT teams, maintaining every layer becomes a capacity problem. And the gap is often not a layer nobody thought about; it's just a responsibility that nobody has clearly owned.
A layer nobody owns is not a secure layer.
This is the work we do. DataYard manages the infrastructure behind business systems and applications. Depending on the environment and the scope of the engagement, that can include operating system patching, 24/7/365 monitoring, network and firewall management, endpoint detection and response, and backup and recovery.
Working together, those layers do more than they could do separately. When paired with other layers, monitoring has context about the infrastructure it is watching. Backup and recovery are planned around the systems they protect. And with one team accountable for more of the environment, there are fewer gaps between vendors for a problem to fall into.
Not every layer will be ours. Application maintenance, user access, and staff training may sit with your team, a development partner, or another provider. We can help tell you which is which.
Start with a conversation about what you are running, which layers have a clear owner, and how you would recover from an incident.
Frequently Asked Questions: Layered Security
What is layered security?
Layered security, also called defense in depth, means an attacker has to get past more than one cybersecurity control. Defenses are built to overlap, so a gap in one is covered by another. Typical layers include patching, access control, network controls, monitoring and detection, backup and recovery, and incident response.
How is layered security different from defense in depth?
The terms are often used interchangeably, although some practitioners distinguish between them. Defense in depth can refer more specifically to placing multiple controls along the same attack path, while layered security can describe the many different types of controls across an environment. In practice, both share the same principle: no single control should be load-bearing.
What are the layers in layered security?
Many cybersecurity frameworks list six layers, organized by control type: physical security, perimeter and network security, endpoint protection, data security, identity and access management, and human or administrative controls. An alternative view organizes the same architecture by function: patching, access control, network controls, monitoring and detection, backup and recovery, and incident response. The second view can be more useful for assigning ownership of each area, because it describes what each layer does rather than where it sits.
Why is patching not enough on its own?
Patching only addresses vulnerabilities that are known, disclosed, and fixed. It does nothing about the time period before a patch exists, the period before it is installed, or an attack that does not rely on a vulnerability. It is one layer, and an important one, but it works best when other layers cover what it cannot.
How many layers does a small business need?
There is no fixed number. A practical starting point is making sure each of the six functions above is assigned to someone, whether internal staff or a provider. The common failure is not a missing layer, but having a layer nobody owns, and therefore isn't thinking about or regularly reviewing.
What should we do if there is no patch available?
Shift attention to the layers that do not depend on one. Limit access, watch for unusual behavior, confirm backups are current and able to be restored, and know how critical operations would continue manually if needed.
Who is responsible for each layer in a hosted environment?
Responsibilities vary significantly by hosting model and provider. Application maintenance may belong to a development team, while operating system patching, monitoring, backups, or infrastructure security may be handled internally or by a managed provider. What matters is documenting those responsibilities explicitly so neither side assumes the other is covering them.
You Can't Control When the Next Vulnerability Appears
Three incidents. Three completely different stories, but all could benefit from layered security.
Nobody can predict which vulnerability, compromised tool, or technique will arrive next. What you can influence is how many layers stand between one problem and a much larger one.
Keep systems current. Reduce unnecessary access. Watch the environment. Keep backups that actually restore. Know who owns each layer. Have a response plan before you need it.
Layered security is not one patch, one product, or one person watching a dashboard. It is a set of controls arranged so that any single failure is survivable.
Not Sure Who Owns Each Layer?
Not sure who owns each layer of your infrastructure? Talk with a DataYard engineer about your current environment, how it is protected, and how you would recover from an incident.
References
- WordPress. "WordPress 7.0.2 Release." July 17, 2026. https://wordpress.org/news/2026/07/wordpress-7-0-2-release/
- Huntress. "Critical N-able N-central Vulnerability and Active Exploitation." August 2026. https://www.huntress.com/blog/n-able-vulnerability-exploitation
- The Hacker News. "Coordinated Cyberattack Targets 30+ Minnesota Water Systems as One Plant Goes Offline." July 2026. https://thehackernews.com/2026/07/coordinated-cyberattack-targets-30.html
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
Data center power redundancy is about more than just backup equipment. It's how utility power, UPS systems, backup generation, and transfer systems are designed to work together. Here's what the terminology means, what to ask a provider, and how DataYard's Dayton, Ohio facility is built to support private cloud and colocation clients.
What Is Data Center Power Redundancy?
When utility power is disrupted, the infrastructure supporting your critical systems becomes especially important.
Data center power redundancy is the practice of designing additional capacity and backup systems into a facility's electrical infrastructure to reduce the risk that a single component failure or utility disruption affects operations.
Backup equipment alone doesn't make a facility resilient. What matters is how each component works together as part of the overall power architecture.
Depending on the facility, a layered approach may include:
- Utility power: The facility's primary source of electrical power.
- UPS battery systems: Conditioned power and immediate short-term continuity if / when utility power is disrupted.
- Backup generation: Additional power designed to support operations during longer utility outages.
- Power transfer systems: Infrastructure designed to transition between available power sources.
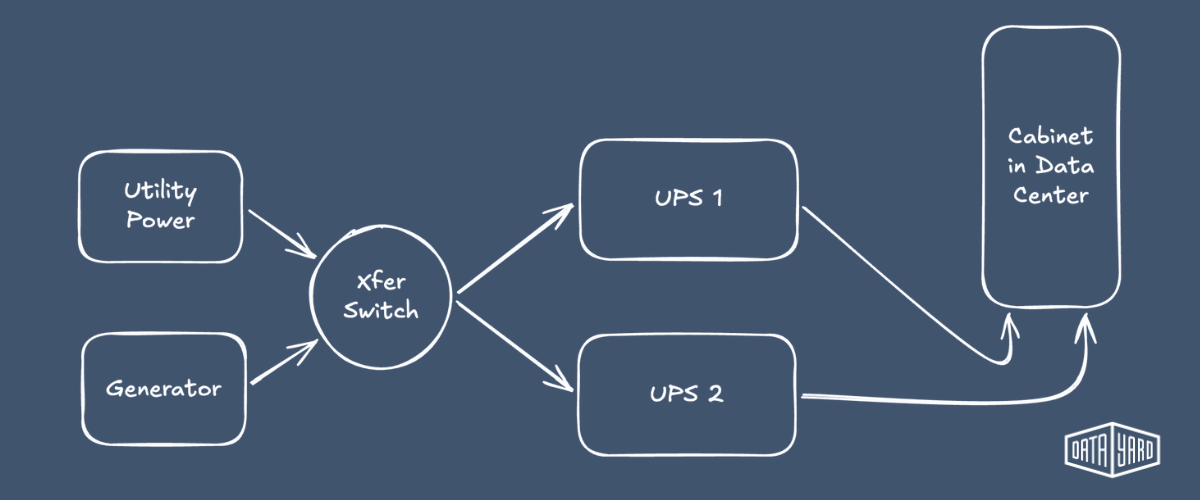
Effective data center power redundancy depends not only on the equipment in place, but also on how the overall system is designed, monitored, maintained, and tested.
Understanding Data Center Redundancy: N, N+1, and 2N
When evaluating a data center, you'll often see infrastructure redundancy described using "N notation."
N
Represents the capacity required to support normal operations without additional redundant capacity.
N+1
Provides the capacity required for normal operations, plus at least one additional component or unit of capacity. Depending on the overall system design, this additional capacity can allow required operations to continue when a component becomes unavailable.
2N
Generally refers to two independent systems, each designed with sufficient capacity to support the required load.
These terms describe different approaches to redundancy, but the notation alone doesn't provide a complete picture of a facility's resilience. How power sources, UPS systems, backup generation, transfer systems, monitoring, maintenance, and testing work together is also important.
The appropriate architecture depends on the facility, the workloads being supported, and an organization's availability requirements.
How DataYard Approaches Data Center Power Redundancy
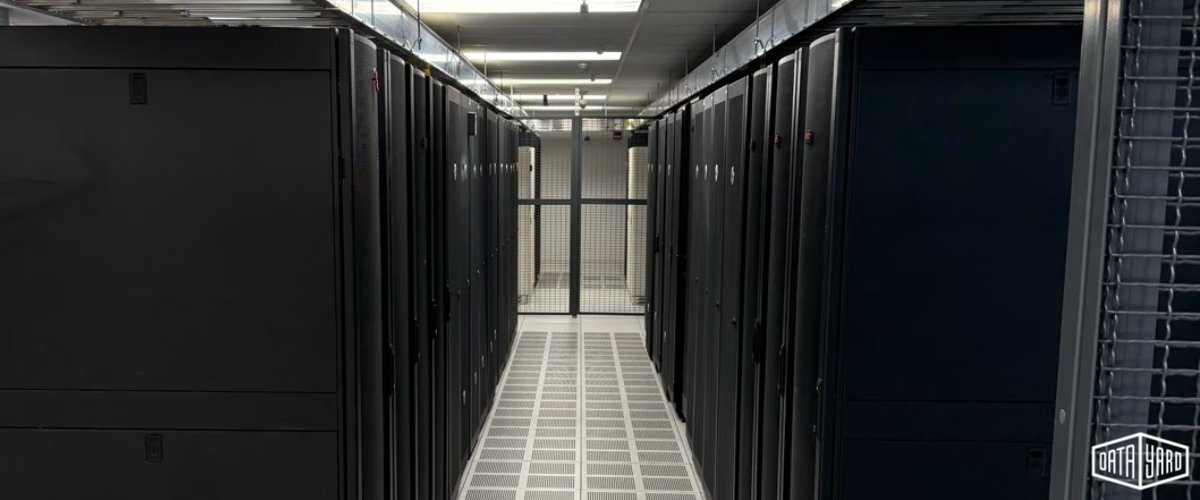
DataYard's Dayton data center uses multiple layers of infrastructure designed to support reliable operations.
Key infrastructure and facility attributes include:
- N+1 UPS systems
- N+1 power management modules, controlling two diverse utility power circuits
- N+1 cooling redundancy
- A natural gas generator for extended utility outages
- Four diverse fiber circuits, providing 40G+ to the internet
- A Tier 3 design
- SOC 2 Type 2 Accredited
Together, these systems and facility attributes support the physical infrastructure behind DataYard's private cloud environments and the equipment our colocation clients house within the facility.
Because the generator is connected to a natural gas supply, it eliminates reliance on onsite fuel storage and scheduled fuel deliveries as part of extended outage planning.
These systems are part of the infrastructure supporting DataYard's 99.999% uptime guarantee, as well as the organizations that depend on reliable access to business-critical systems.
What Data Center Power Redundancy Means for Cloud and Colocation Clients
Cloud services rely on physical infrastructure, whether that infrastructure is operated by a cloud provider, housed in a private data center, or distributed across multiple environments.
For clients running private cloud environments at DataYard, the facility's power, cooling, networking, and other systems provide the physical foundation for the servers' compute and storage resources supporting their workloads.
For colocation clients, the connection to the facility's physical infrastructure is direct. Their physical servers and networking equipment are housed within the data center and depend on the facility's power, cooling, connectivity, and security infrastructure.
Hybrid environments introduce additional considerations. Applications and data may span private infrastructure, colocated equipment, and / or public cloud platforms, with networks and services connecting those environments.
For organizations running business-critical systems, resilient facility infrastructure can help support:
- Continued operations during extended utility disruptions
- Backup power capability beyond UPS battery systems
- Business continuity and disaster recovery strategies that depend on reliable underlying infrastructure
Power redundancy alone doesn't create a complete business continuity or disaster recovery strategy. Applications, data, backups, replication, network connectivity, security, and documented recovery procedures all play a role, and resilient physical infrastructure provides an important foundation for those systems.
5 Questions to Ask About Data Center Power Redundancy
If you're evaluating a data center or colocation provider, understanding the facility's approach to power resilience can help you make a more informed decision.
Consider asking:
-
What happens if utility power is unavailable for an extended period?
Understanding how a facility is designed to operate beyond the immediate backup period provided by UPS systems can provide insight into its broader power resilience strategy.
-
What roles do UPS systems and backup generation play?
UPS and generator systems typically serve different purposes. Ask how they work together within the facility's overall power architecture.
-
How is backup generation supported during a prolonged utility disruption?
Ask about the facility's approach to generator runtime and how its fuel strategy supports extended outage planning.
-
How are transitions between power sources managed?
Understanding how the facility transitions from utility power to backup systems can help you evaluate the overall architecture.
-
How are redundant systems monitored, maintained, and tested?
Redundant equipment is only part of the equation. Ongoing monitoring, preventive maintenance, and testing are also important considerations when evaluating infrastructure resilience.
Clear answers to these questions can help you determine whether a facility's power architecture aligns with your organization's requirements for availability, continuity, and risk management.
Is Your Infrastructure Prepared for an Extended Utility Disruption?
The best time to understand your infrastructure's resilience is before a disruption occurs.
Whether your servers are located in your office, a colocation facility, or a private cloud environment, consider what would happen if utility power became unavailable for an extended period.
How long could your current infrastructure continue operating? What systems would be affected? How would a disruption affect your employees, customers, and business operations?
Understanding those dependencies can help you identify potential risks and determine whether your current infrastructure strategy provides the level of resilience your organization requires.
If you're uncertain how your current infrastructure would perform during a prolonged utility disruption, DataYard can help you evaluate your requirements and discuss practical options for improving resilience.
Frequently Asked Questions About Data Center Power Redundancy
What is data center power redundancy?
Data center power redundancy means that a facility has backup systems in place to reduce the risk that a single component failure or utility disruption affects operations.
Depending on the facility, the architecture may include UPS battery systems for immediate continuity, redundant power capacity, backup generation for longer outages, and systems designed to transition between available power sources.
How is generator backup different from UPS backup?
UPS systems provide immediate continuity when utility power is disrupted. Backup generators are designed to provide power during longer utility disruptions.
The two serve different but complementary roles within a data center's power architecture.
What power redundancy does DataYard's Dayton data center have?
DataYard's Dayton facility has N+1 UPS systems and power management modules, and redundant, A&B power feeds for client and internal use, fed by diverse power circuits.. The facility also has N+1 redundancy for all chiller and cooling equipment, as well as a natural gas generator designed to provide backup power capability during extended utility disruptions.
Why does DataYard use a natural gas generator?
A natural gas generator provides backup power capability during extended utility outages and is one component of DataYard's broader approach to infrastructure resilience at the Dayton facility.
How does power redundancy affect disaster recovery planning?
Power redundancy isn't a disaster recovery strategy by itself, but resilient facility infrastructure provides an important foundation for business continuity and disaster recovery planning.
Applications, backups, replication systems, storage, and network connectivity all depend on the infrastructure supporting them. Reducing exposure to facility-level power disruptions can help those systems remain available and operate as designed.
Does DataYard offer colocation services in Ohio?
Yes. DataYard provides colocation services from its data center in Dayton, Ohio, with flexible shared and dedicated cabinet options for organizations that need space for their server and networking equipment.
Clients can use DataYard's data center infrastructure while maintaining control of their own IT infrastructure and accessing local technical expertise.
Planning for Infrastructure Resilience?
Whether you're evaluating private cloud, colocation, or a hybrid environment, understanding the physical infrastructure behind your critical systems is an important part of planning for availability and continuity.
DataYard can help you evaluate your current environment, identify infrastructure requirements, and determine an approach that aligns with your workloads, availability needs, and long-term technology strategy.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
The cloud, colocation, or both? This guide compares the two on cost, control, security, and performance, so you can decide where each of your business-critical systems actually belongs.
For years, businesses heard a simple message: move everything to the cloud. In practice, infrastructure decisions have always been more nuanced.
Cloud is the right home for some workloads. Colocation makes more sense for others. And for many businesses, the best approach involves a mix of environments. With this guide, we’ll look at where each approach fits, what questions to ask, and how to decide where your critical systems belong.
If you already own mission-critical hardware, need greater control over your infrastructure, or are reevaluating rising cloud costs, placing that hardware in a purpose-built data center may be worth considering. The goal isn’t to choose a side. It’s to build an infrastructure strategy that fits the way your business operates.
Colocation vs. Cloud: The Short Version
The differences between colocation and cloud start with who owns the hardware, but they don't end there. That ownership model shapes how you pay for infrastructure, how quickly you can scale, how much direct control you retain, and how the environment is managed.
One way to think about it is: renting versus owning. The cloud gives you access to infrastructure without owning the underlying hardware, while colocation lets you retain ownership of your equipment without having to operate the facility that houses it. The better fit depends on the workload, the level of control you need, and how you want to manage infrastructure costs.
Neither is universally "better." The right choice depends on what a given system needs, what you already own, and how much control you want to have.
| Attribute | Colocation | Cloud |
|---|---|---|
| You own | The hardware | Nothing physical |
| Cost model | Hardware CapEx plus recurring costs for space, power, connectivity, and services | Primarily OpEx through ongoing usage or service-based billing |
| Control | Full control of your equipment | Provider controls the entirety of the physical layer |
| Scaling | Requires acquiring and installing hardware | Fast, on demand |
| Best for | Owned, mission-critical, or specialized hardware | Variable workloads and rapid growth |
| Where data lives | You know exactly where data is housed | Depends on the provider and configuration |
The table gives you the high-level comparison. To understand which model fits a specific workload, it helps to look more closely at how each one works, starting with colocation.
What Is Colocation?
Colocation is when you place your own hardware in a third-party data center. You still own and control the servers, data storage, and networking gear inside of your cabinet. What changes is the environment around it.
Instead of running your infrastructure in an office closet or an aging on-premises server room, your equipment lives in a facility built specifically to keep critical infrastructure operating, with features such as redundant power, backup generators, high-capacity cooling, diverse internet connectivity, and layered physical security.
That environment matters more than it might seem. Among data center operators surveyed by the Uptime Institute for its 2026 Annual Outage Analysis, more than half said their most recent major outage cost over $100,000, and one in five said it topped $1 million. Those numbers underscore why resiliency matters when critical infrastructure is involved. Purpose-built data centers are designed with redundant systems intended to reduce infrastructure-related risks to the equipment they house.
Colocation tends to make sense when you already own mission-critical hardware, have specialized networking, application, or licensing requirements, want to retain ownership of your equipment, or need to know exactly where your data physically sits. It's a common landing spot for organizations that are done managing a facility but not done owning their infrastructure. The appeal is getting the best of both: you keep full control of your hardware and your data, while the facility handles the power, cooling, connectivity, and physical security that are hard to replicate in an office.
Thinking about moving to a colocation data center?
Our recent guide walks through the logistics: Things to Consider When Moving Equipment to a Colocation Data Center. Learn more about our purpose-built colocation in Dayton, Ohio: Data Center Colocation.
Colocation gives you a way to keep the hardware you own without operating the facility around it. Cloud takes a different approach by removing hardware ownership from the equation altogether.
What Is "The Cloud"?
The cloud flips the ownership model. You don't buy or maintain the underlying physical server hardware. Instead, you use compute, storage, networking, and other services running on infrastructure owned by a provider, and you pay based on the services or resources you use.
The cloud provider handles the physical layer: the servers, facility, maintenance, and hardware replacements. Your team, or a managed cloud provider, works at the software, configuration, and management layers. Resources can typically be scaled up or down without ordering and installing new physical equipment.
The cloud tends to make sense when your workloads are variable or seasonal, you're growing quickly and need to scale without hardware lead times, you'd simply rather not own or refresh hardware, or you need to spin environments up and down frequently.
It's also worth knowing there are public and private clouds. Public clouds like Amazon AWS and Microsoft Azure run on shared provider infrastructure and offer pay-as-you-go scalability, so you can add capacity on demand.
A private cloud gives you many of the same benefits while keeping your workloads on dedicated resources, with greater visibility into where your data resides, without owning the underlying physical gear yourself.
If the right cloud setup isn't obvious, cloud management and consulting teams can help you design a cloud layout that fits your workloads, controls costs, and keeps the environment running well over time. Whichever fits, our team can help you design and manage it.
Understanding how each model works is the first step. The bigger question is how those differences affect the factors businesses actually have to weigh: cost, control, security, performance, and scalability.
Colocation vs. Cloud: A Closer Look
The short version covers the headline differences. Here's where the decision actually gets made.
Cost: CapEx vs. OpEx
This is often a major factor in the decision, and it's rarely as simple as one being "cheaper" than the other.
With colocation, hardware is typically a capital expense. You purchase and own the equipment, while space, power, connectivity, and related data center services are ongoing operating expenses. Those recurring facility costs are generally more predictable, which can make long-term infrastructure spending easier to forecast.
The cloud is primarily an OpEx model. There's no physical hardware to buy, but you pay on an ongoing basis for the resources and services you consume. Depending on the environment and pricing model, those costs can become harder to predict as usage grows. Charges that are easy to overlook up front, such as data transfer (egress) fees for moving data out of a provider, can add up unexpectedly over time.
This isn't a fringe concern. Managing your business' cloud spend has ranked as the top cloud challenge for four straight years, cited by 85% of organizations in Flexera's 2026 report. The report also found estimated wasted cloud spend at around 29%.
The practical takeaway: the cloud can be financially attractive for short-term, variable, or rapidly changing workloads, while colocation can offer greater long-term cost predictability for steady, always-on workloads running on hardware you already own.
Actual total cost depends on the details, including hardware refresh cycles, staffing, licensing, bandwidth, power requirements, and how fully you use the resources you're paying for. The right comparison is a workload-specific total cost analysis, not simply one monthly bill against another.
Cost is only one part of the equation. The ownership model also determines how much direct control you have over the infrastructure running your workloads.
Control and Ownership
With colocation, you keep full control of your hardware and its configuration. You decide what equipment runs, how it's configured, and when it changes. For teams with specific licensing, performance, or hardware requirements, that level of control can matter.
With the cloud, the provider controls the physical layer and, depending on the service, may manage additional parts of the technology stack. You gain convenience and flexibility while giving up some direct control over the underlying infrastructure.
For many workloads, that's a worthwhile trade. For others, maintaining direct hardware control is an important requirement.
The flip side of that control is responsibility: with colocation, maintaining and updating your own hardware is on you, though many providers offer remote hands and support to handle physical tasks when you can't be on-site. With the cloud, the provider absorbs much of that operational load as part of the service.
Even then, the cloud isn't entirely hands-off. You still manage the cost, configuration, and architecture, which is why some teams bring in cloud management and consulting assistance to keep spend and setup optimized over time.
That difference in control also shapes how security responsibilities are divided and how organizations approach specific compliance or governance requirements.
Security and Compliance
Both models can be highly secure, but responsibility sits differently.
In colocation, physical security comes from the facility through measures such as access controls, surveillance, and restricted entry, while you retain responsibility for securing your own systems, applications, and data.
In a public cloud, security typically follows a shared responsibility model between you and the provider. Major cloud platforms offer extensive security capabilities, including region selection, encryption options, identity controls, and granular access management.
The more useful distinction isn't which model is "more secure." It's which model gives your organization the right level of control and visibility for its specific requirements. Organizations with particular data-residency, hardware-control, or audit requirements may prefer the more direct physical control available through colocation or certain private cloud environments.
Beyond security and compliance, the underlying infrastructure can also affect how consistently workloads perform and how much flexibility you have to optimize for specific requirements.
Performance and Latency
Colocation gives you dedicated hardware, which can provide consistent, predictable performance. Because you control the equipment and its configuration, you can design the environment around the specific performance requirements of your workloads.
Cloud performance is generally strong, and public cloud providers offer a wide range of configurations, including dedicated resources and options designed for workloads with specific performance requirements.
The distinction comes down to workload needs. Shared cloud configurations may introduce variables that dedicated environments are designed to avoid, while the cloud provides significantly more flexibility to add or change resources. For most applications, either approach can deliver excellent performance when properly architected. For latency-sensitive or highly specialized systems, the underlying infrastructure deserves closer consideration.
Consistent performance matters, but so does the ability to add capacity when demand changes. That's where the scalability differences between the two models become especially important.
Scalability
This is where the cloud has a clear advantage.
Need more capacity? Cloud resources can often be added in minutes without purchasing or installing new hardware. For workloads that spike, grow quickly, or change frequently, that flexibility is difficult to match.
Colocation scales too, but on a hardware timeline. Adding capacity means acquiring, installing, and configuring additional equipment, which requires planning.
For steady, predictable workloads, that may not be a problem. For highly unpredictable or short-lived demand, cloud elasticity can be a significant advantage. This is also where the two models complement each other: some businesses keep steady systems in colocation and lean on cloud to absorb short-term spikes, which is the basic logic behind a hybrid setup.
Taken together, these differences point back to the same conclusion: the right environment depends on the workload. And in many cases, choosing one model for every system isn't necessary.
What About Hybrid?
For many businesses, the answer isn't just colocation or the cloud. It can be both.
Hybrid infrastructure combines multiple environments -- colocation, private cloud, public cloud, and sometimes on-premises systems, so each workload can run wherever it fits best.
Hybrid infrastructure is widely adopted. According to Flexera's 2026 State of the Cloud Report, 73% of organizations operate hybrid estates spanning public cloud, private cloud, and on-premises or colocated hardware.
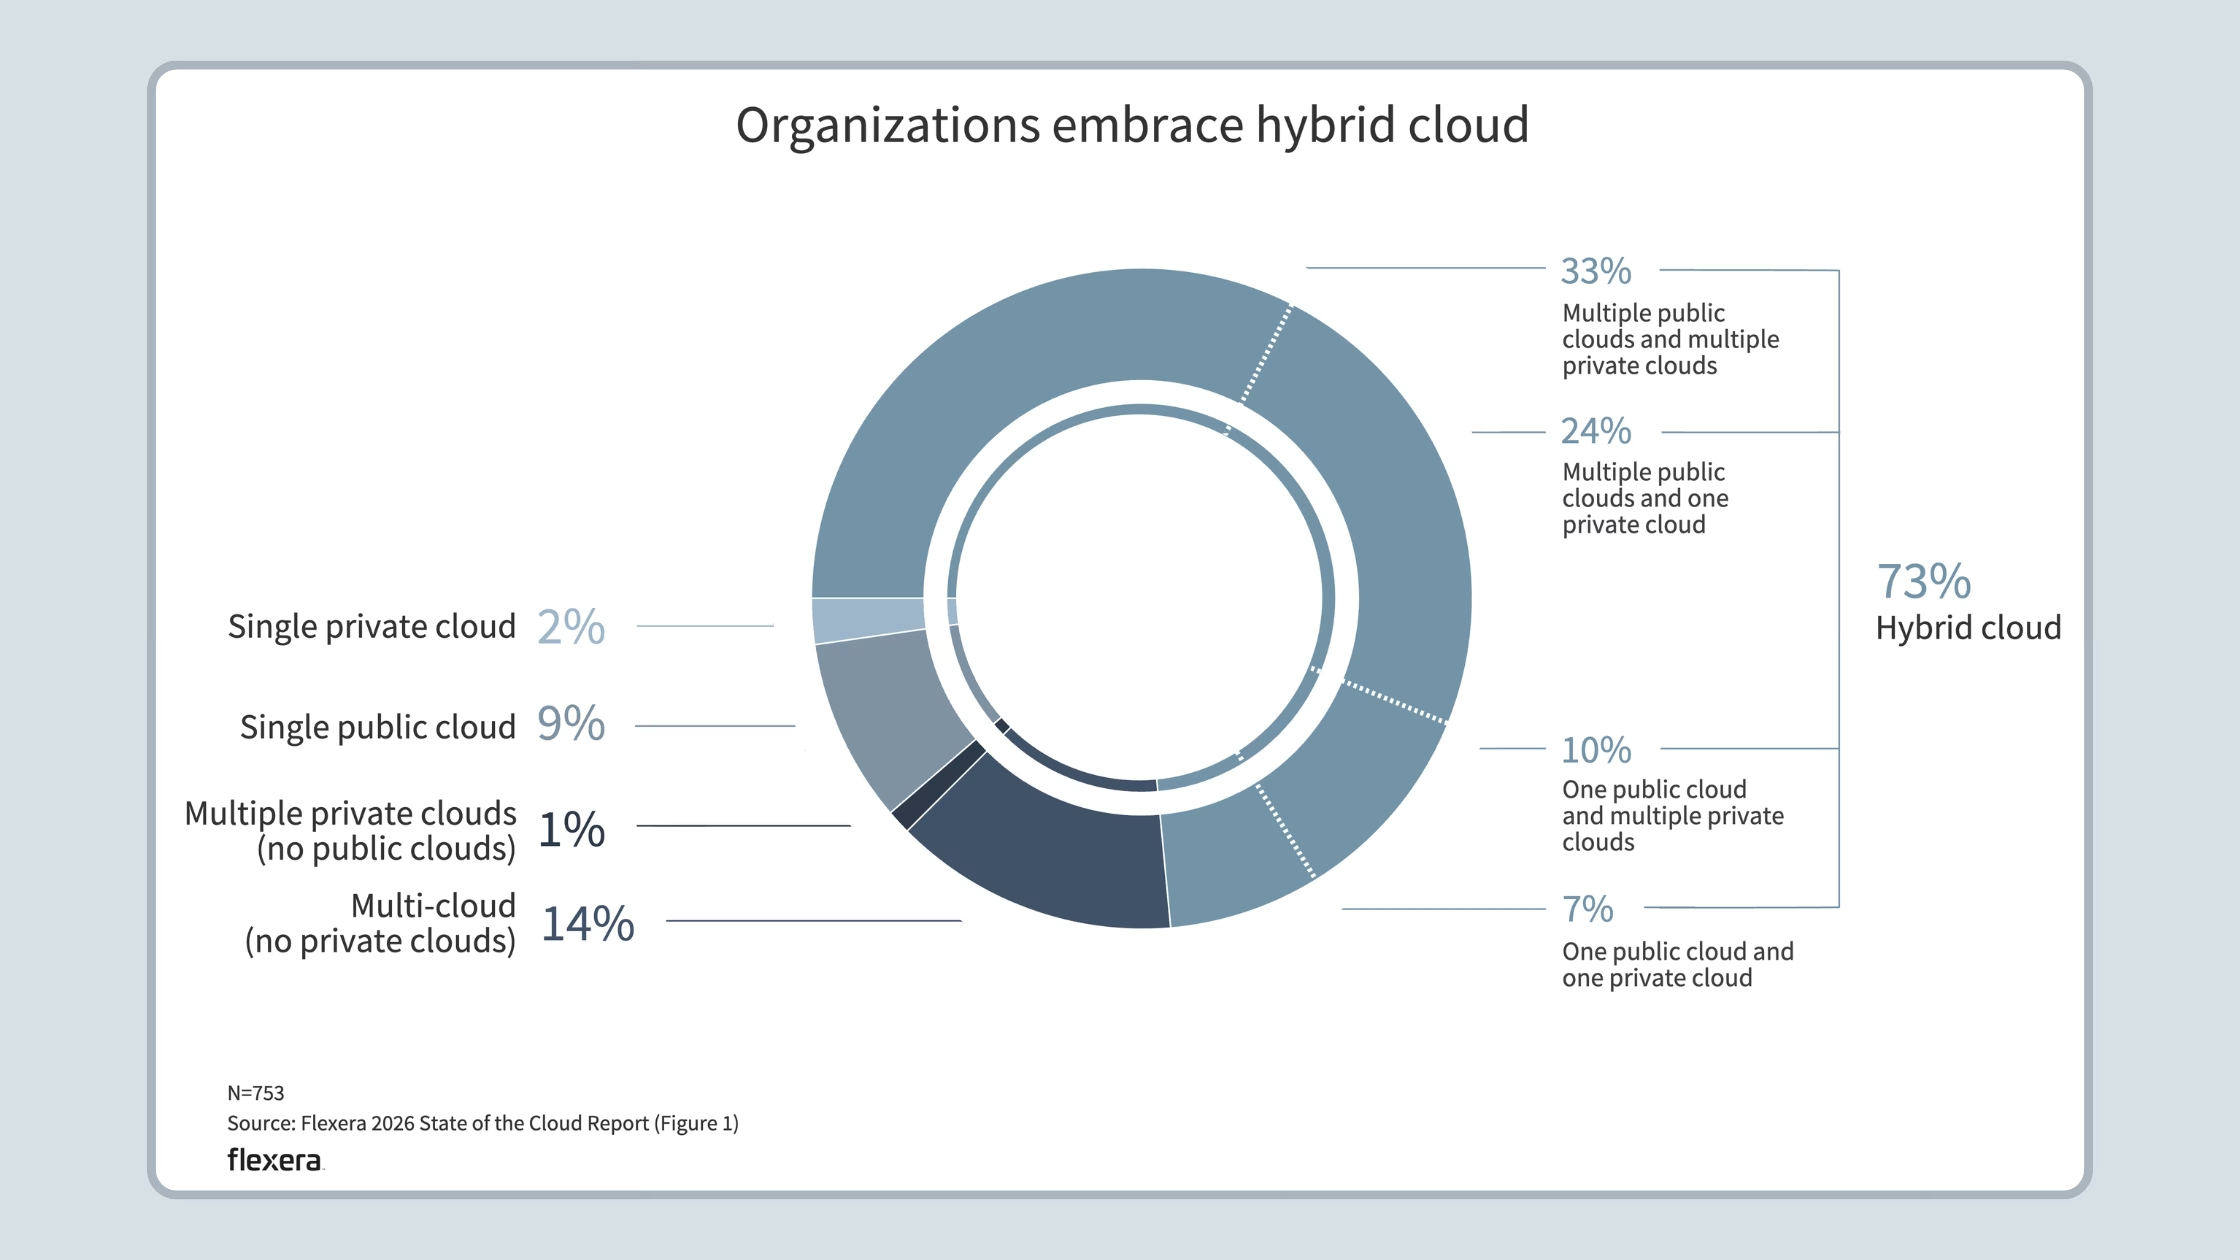
There's a reason it's so common. Workloads move to (or stay out of) the public cloud for all kinds of reasons, including performance, compliance, data sovereignty, latency, control, and economics. No single environment is the right fit for every system.
A hybrid approach lets you match each workload to the right home. Steady, business-critical systems and hardware you already own may be strong candidates for colocation. Variable, fast-scaling, or short-lived workloads may be better suited to the cloud. In practice, that often looks like keeping a core production system on dedicated hardware in a data center while using a cloud environment to absorb seasonal traffic spikes, with the two connected so they work as one environment.
Done well, a hybrid setup isn't a compromise. It's an intentional architecture that balances cost, control, performance, and flexibility.
So Which One Should You Choose?
The right answer depends on the specific workload. A few questions can help point you in the right direction:
- Do you already own mission-critical hardware you want to keep using? Colocation is worth a serious look.
- Are your workloads highly variable or growing quickly? Cloud flexibility may be the better fit.
- Do you need predictable, easily-forecast costs for steady, always-on systems? Colocation may come out ahead over time.
- Do you need to spin environments up and down frequently? The cloud is built for that.
- Do you have specific data-residency, hardware-control, or audit requirements? Colocation and certain private cloud environments may make those requirements easier to address.
Many organizations ultimately land on some mix. The goal isn't to pick a side. It's to put each system where it runs best.
Making those decisions workload by workload can create a better-fit infrastructure strategy, but it also requires expertise across multiple environments. That's where having one team that understands cloud, colocation, and hybrid infrastructure can help.
Why DataYard
The hard part usually isn't picking cloud or colocation (or a mix of both). It's figuring out which workloads belong where, and then running them well once they're placed. That's the work we do.
DataYard designs and manages infrastructure across private clouds, public clouds, and colocation setups. That means we can start with your workloads and requirements, then determine which environment, or combination of environments, makes the most sense. When the right answer is a hybrid mix, our team can help architect and manage the pieces together.
Our own private cloud and colocation infrastructure are housed in our SOC 2 Type 2 accredited data center in downtown Dayton, with redundant power, N+1 cooling, diverse connectivity, and 24/7 support from Ohio-based engineers. Both services are financially-backed by a 99.999% uptime guarantee.
For public cloud and hybrid environments, our team brings experience across platforms and technologies including AWS, Azure, and Cloudflare.
The result is infrastructure designed around what your workloads actually need, backed by engineers who understand the environment they're managing.
Not Sure Where Your Workloads Belong?
There's no single right answer, and the best setup usually depends on details specific to your business.
If you'd like a second perspective, our engineering team can help you weigh the options and design an environment that fits, whether that's a private cloud, a public cloud, colocation, or a mix.
DataYard has operated its own data center in downtown Dayton since 1995, and we help organizations host and manage mission-critical infrastructure.
FAQ: Colocation vs. Cloud
Still weighing the options? These common questions cover a few of the issues businesses often consider when comparing colocation and cloud.
Is colocation cheaper than the cloud?
It depends on the workload. Colocation typically involves an upfront investment in hardware plus recurring costs for data center space, power, connectivity, and related services. For steady, always-on systems, that model can provide greater long-term cost predictability. The cloud avoids the upfront cost of purchasing physical hardware but typically involves ongoing service or usage-based costs, which can be attractive for variable workloads, but may become harder to predict as usage grows. Actual total cost depends on hardware refresh cycles, staffing, licensing, bandwidth, power requirements, and utilization, so it's worth modeling the options for your specific systems.
Is the cloud more secure than colocation?
Neither is inherently more secure. Both can be highly secure when designed and managed well. The difference is where responsibility sits and how much direct control you retain. Organizations with specific data-residency, hardware-control, or audit requirements may prefer the more direct physical control available through colocation or certain private cloud environments.
Should I use colocation or cloud, or both?
Many organizations use both, placing steady or already-owned systems in a colocation data center while using the cloud for workloads that benefit from rapid scaling. Deciding which workloads go where isn't always obvious, though, and it's a common reason businesses bring in a partner who works across colocation, private cloud, and public cloud infrastructures to assess their environment and design the right mix.
Are companies moving from cloud back to colocation?
Some organizations move specific workloads out of the public cloud, often for reasons such as cost predictability, data transfer (egress) fees, performance consistency, or tighter control and compliance. This practice is sometimes called cloud repatriation. It's less a wholesale reversal than a sign that businesses are evaluating where individual workloads fit best. For many organizations, the result is a hybrid infrastructure strategy that combines multiple environments rather than moving everything in one direction.
How do I know which workloads belong where?
Start by looking at each system's cost profile, performance requirements, growth patterns, existing hardware, and compliance or governance needs. Steady, business-critical, or hardware-specific systems may be good candidates for colocation. Variable, seasonal, or rapidly scaling systems may be better suited to the cloud. The important thing is to evaluate the workload first rather than choosing an infrastructure model and forcing every system into it.
What is a hybrid infrastructure strategy?
A hybrid infrastructure strategy intentionally combines multiple environments, which may include public cloud, private cloud, colocation, and on-premises infrastructure. Rather than forcing everything into one model, each workload is placed in an environment based on factors such as cost, control, performance, scalability, and operational requirements. The different environments can then be connected and managed as part of a broader infrastructure strategy.
Talk With Our Team
DataYard has operated its own data center in downtown Dayton since 1995, and we help organizations host and manage mission-critical infrastructure.
Citations
Flexera. "2026 State of the Cloud Report."
Uptime Institute. "Annual Outage Analysis 2026."
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup

Colocation Migration Checklist
If you're planning a migration to a colocation facility, here's a quick checklist of the major planning items to keep in mind. We'll cover each one in more detail throughout the rest of this guide.
- Inventory all equipment
- Research colocation facilities
- Confirm carrier connectivity
- Test backups
- Design rack layout
- Document rollback plan
- Schedule downtime
- Verify DNS and firewall changes
Why Businesses Move Equipment to a Colocation Facility
Most colocation projects don't start with a technical decision.
They start with a business problem.
An office move. A recurring outage. Rising utility costs. A server room that's one power surge away from a bad day. Whatever the trigger, the pattern is usually the same: something forces the issue, and suddenly relocating infrastructure makes a lot more sense than it did six months ago.
Common triggers include:
- Power or internet outages at the office
- An office move or shift to remote work
- Rising utility and facility costs
- Aging server rooms with no infrastructure redundancy
- A data center that's closing or underperforming
- Growth that's outpaced existing infrastructure
- Compliance or security requirements that the current on-prem can't meet
- A need to retain hardware ownership while offloading the facility burden
Colocation hits a practical middle ground: you keep control of your equipment while gaining access to purpose-built infrastructure with redundant power, reliable cooling, diverse connectivity, and physical security that most office environments can't match.
If any of those sound familiar, here are a few things to consider before you start unplugging anything.
Document Everything First
Record your inventory before any equipment is disconnected.
Before any equipment is disconnected, document everything you have.
That means servers, storage systems, network switches, firewalls, serial numbers, asset tags, rack locations, IP addresses, VLAN assignments, port mappings, software licenses, virtual machine dependencies, and backup configurations.
During a physical move, things can get disconnected, shuffled, or mislabeled. This is why precise documentation eliminates most of the guesswork during re-installation and helps speed up troubleshooting when something doesn't come back online the way it should.
A migration to colocation is also a good opportunity to identify hardware that can be retired rather than relocated. Avoid moving equipment you no longer need to run operations. With a complete inventory in hand, the next step is making sure your new facility can actually support what you're bringing.
Confirm the New Facility Can Support Your Requirements
Verify the facility supports your current environment and future growth.
Not all colocation data centers are built the same. Before choosing a colocation provider, verify the facility can support both your current environment and future growth.
Items to confirm with colocation facilities:
- Power: Total consumption, redundant A/B feeds, UPS infrastructure, generator backup, and available power density per rack. It's easier to request more power upfront than to negotiate for it after you're installed.
- Cooling: Cooling capacity, airflow design, and hot/cold aisle configuration. Reliable cooling directly affects hardware performance and lifespan, so you want to make sure where you're moving is up to the task.
- Space: Current rack requirements, room to grow, and whether private caging is available if you need it.
- Connectivity: Available internet bandwidth, carrier diversity, and cross-connect options. If you lose an internet upstream provider, carrier diversity is what keeps you running -- most organizations don't think about this until it matters.
- Physical security: Access control, video surveillance, visitor management, and restricted entry areas.
- Accessibility: 24/7 access, after-hours procedures, and proximity to your office. When something fails at 2AM, how fast can you get there?
Once the facility is confirmed, the piece most teams underestimate is network planning, and it needs to start earlier than most expect.
Plan Network Connectivity Early
Work through circuit and carrier requirements well before the move date.
Network provisioning is one of the most common sources of migration delays and one of the easiest to avoid with early planning.
If your environment depends on dedicated circuits, SD-WAN, MPLS, VPNs, or cloud interconnects, start working through those requirements well before the move date. Carrier provisioning timelines are often longer than expected.
Questions to answer:
- Will existing circuits need to transfer?
- Are new circuits required at the new facility?
- Will VPN endpoints or IP address information change?
- Will firewall policies need updates?
Getting ahead of this avoids the frustrating situation where equipment is physically online but traffic isn't reaching it correctly. With connectivity planned, the next decision is how equipment will physically live in the space.
Design Rack Layouts Before Equipment Arrives
Plan the physical layout instead of figuring it out on moving day.
Don't wait until moving day to figure out where things will be installed.
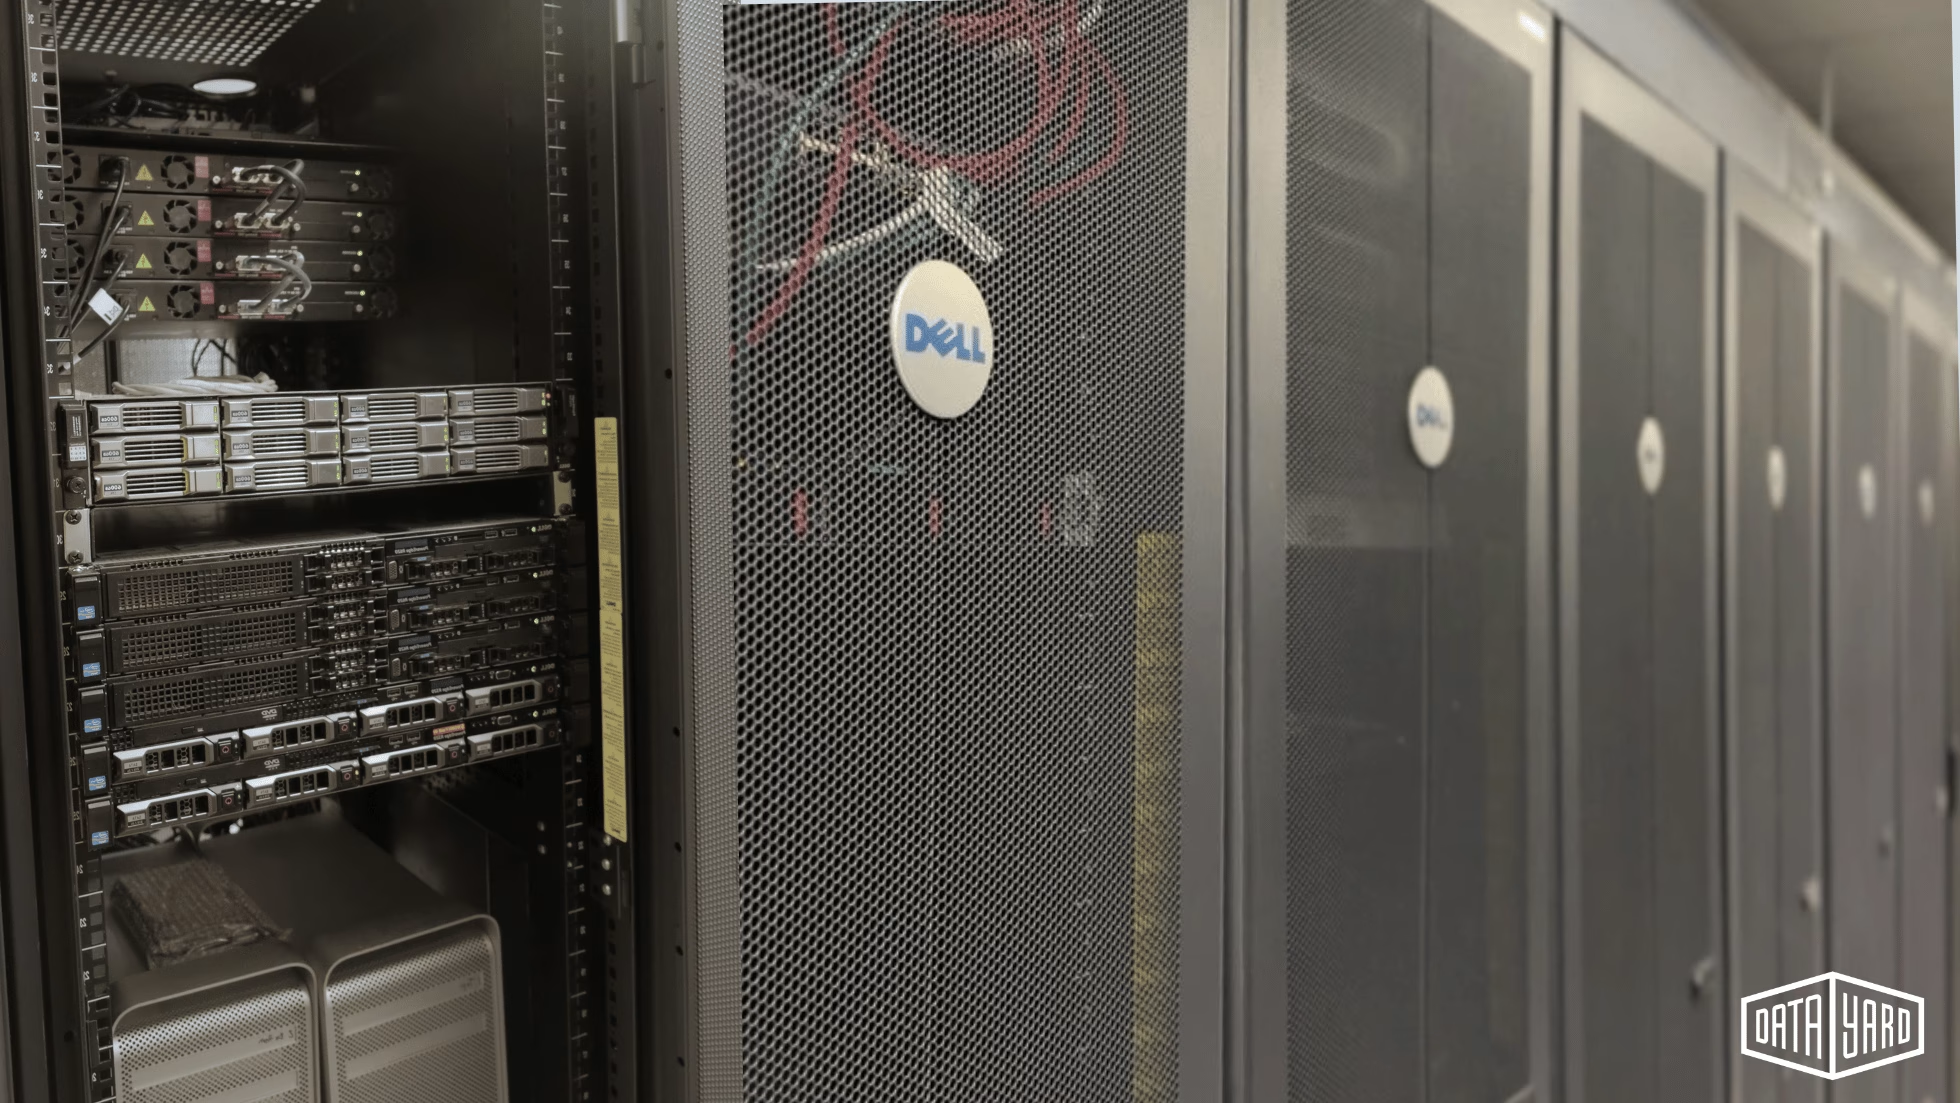
A planned rack design helps avoid cable congestion, airflow problems, uneven power draw across redundant feeds, and limitations on future expansion. Think through weight distribution, cable management paths, serviceability, and where growth will physically fit.
Pre-planned the rack layout helps cut installation time significantly and makes future maintenance much simpler.
Quick Tip
Your colocation provider may be a good resource here. A good one has likely seen hundreds of rack configurations and can help you avoid common layout mistakes before equipment arrives.
When your rack layout is done, the next thing to nail down is your downtime plan and what happens if something doesn't go right.
Plan for Downtime and Build a Rollback Strategy
Control downtime with a deliberate plan and a documented rollback procedure.
Every colocation migration should include a deliberate downtime plan and a documented rollback procedure if something doesn't go as expected.
Before the move begins:
- Schedule the move during off-hours, or on a day when downtime is manageable
- Identify your most critical applications and move them last / turn them on first
- Validate non-critical systems before touching production workloads
- Document rollback procedures in writing, not just in someone's head
- Assign clear ownership for each migration task
- Designate a single point of contact for communication — internally and with affected vendors or customers
The goal isn't to eliminate downtime entirely, but rather to control it. Planned downtime is tolerated. Surprise downtime is not. Clear communication before the move helps set expectations and minimizes surprises.
Before anything gets packed, there's one step that's non-negotiable.
Validate Your Backups
A backup is only valuable if it can actually be restored.
Before equipment leaves its current location: perform fresh backups of all data, export firewall and switch configurations, and verify those backups are actually restorable.
A backup is only valuable if it can be restored successfully -- so test it, don't just confirm it exists.
Even hardware that's been running reliably for years can have a bad day after being transported. Vibration, physical shock, and the stress of a move can surface latent hardware issues. Verified backups mean a hardware failure during transit becomes a recoverable incident rather than a total business disaster. If you don't have a solid backup and recovery plan in place before the move, that's the place to start.
Now the focus shifts to transporting the equipment safely.
Plan the Physical Move Carefully
Server equipment is designed for operation, not transportation.
Server equipment is designed for operation, not transportation. Proper handling matters more than most organizations expect.
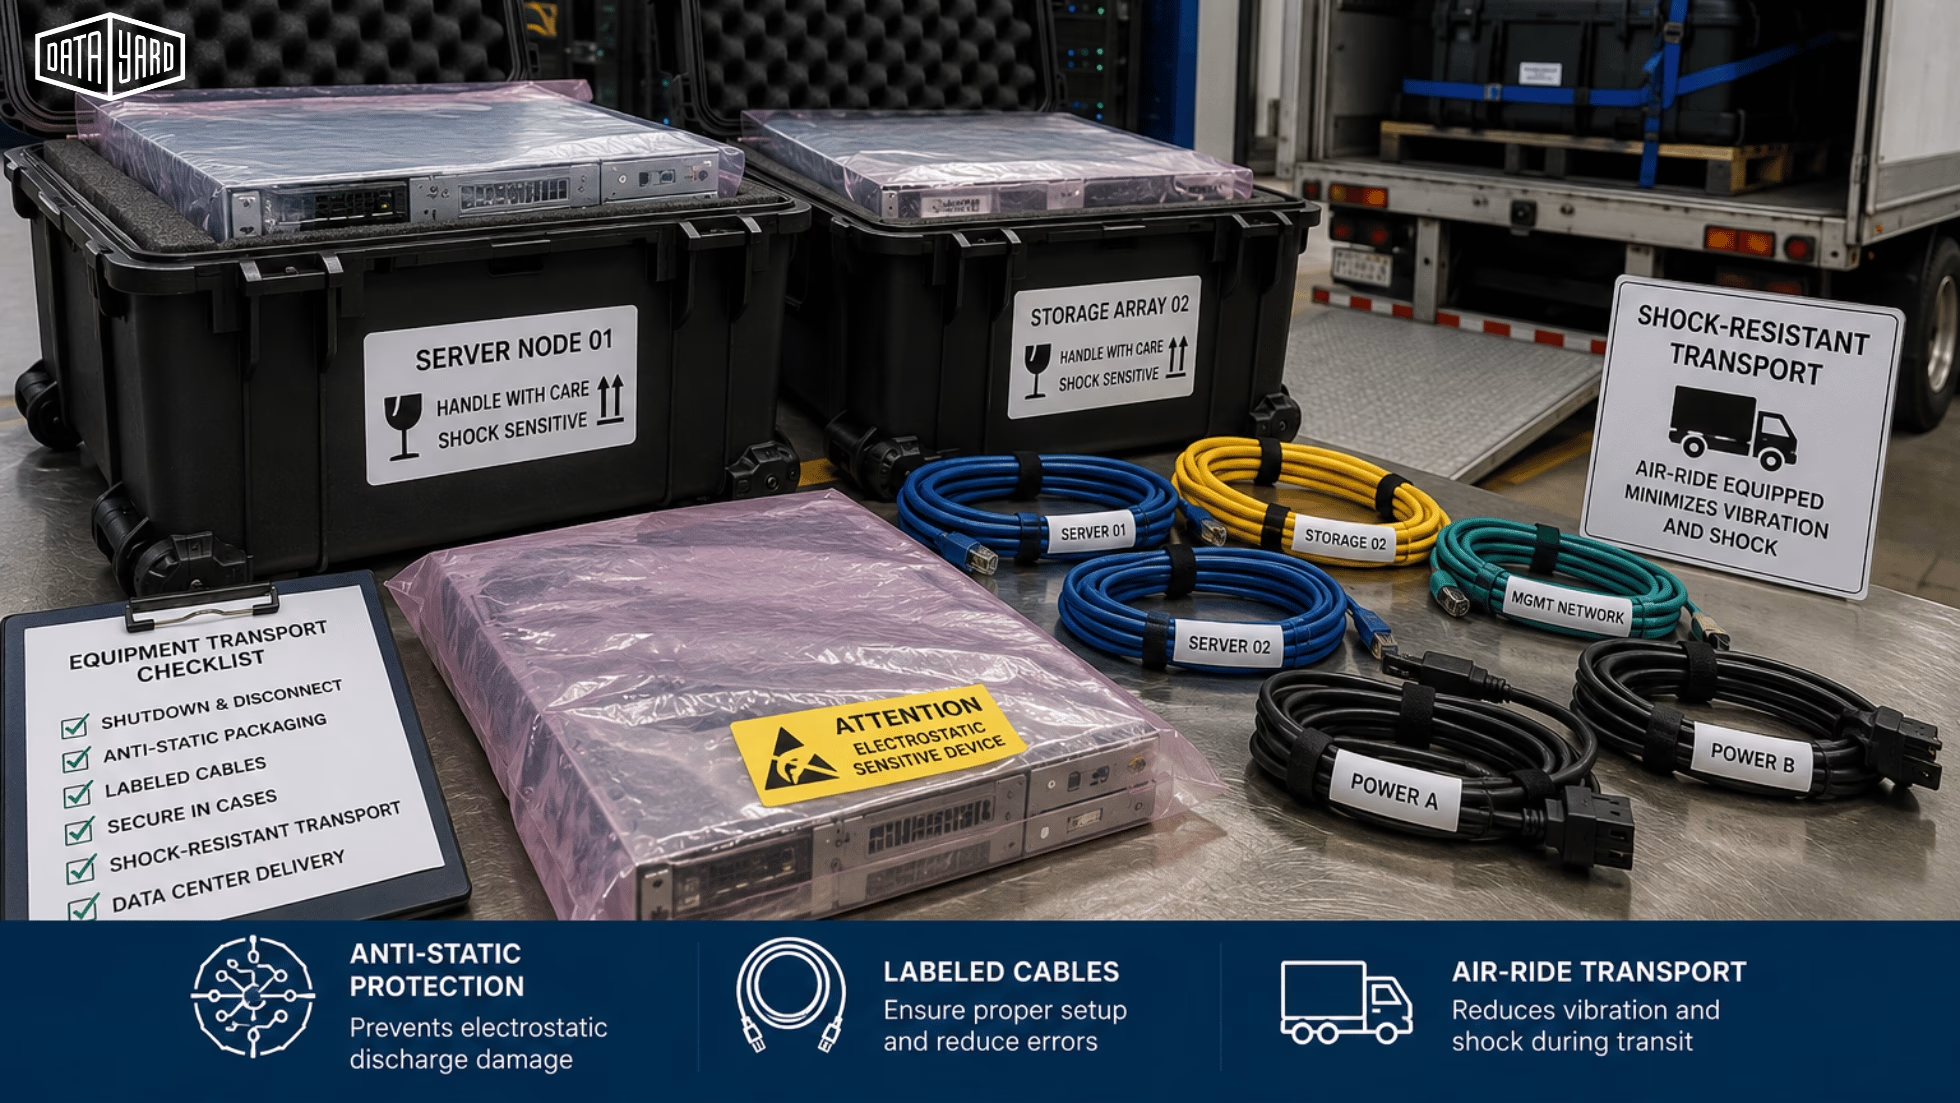
- Packaging: Use anti-static foam, shock-resistant containers, and equipment boxes rated for the weight. Consumer-grade moving materials are typically not appropriate for server hardware.
- Labeling: Before disconnecting anything, label cables, label power connections, document switch ports, and photograph your rack layouts. Photos routinely save hours during reassembly.
- Handling: Follow manufacturer handling and lifting recommendations for all equipment being transported.
- Transportation: Where possible, use vehicles with air-ride suspension and climate control. Vibration during transit causes more hardware damage than most people account for.
- Insurance: Confirm that you have coverage during packing, transit, loading, unloading, and installation. Many standard policies have gaps for equipment in transit -- verify your policy details before the truck pulls out.
Planning a colocation migration?
If you'd like a second set of eyes on your migration plan before moving day, our engineering team can help identify potential risks and answer questions before they become problems. DataYard has been helping organizations relocate and operate mission-critical infrastructure from our Dayton data center since 1995.
Talk With Our Team →Plan for IP Address and DNS Changes
IP and DNS changes are often what keep things from coming back online cleanly.
Once equipment is in place, IP and DNS changes are often what keeps things from coming back online cleanly. If your move involves changing providers or network environments, public IP addresses are likely to change. This is one of the more commonly underestimated issues in a colocation move.
Before the move, review DNS records, firewall rules, VPN configurations, SaaS allow lists, email services, vendor integrations, and geolocation-based restrictions. DNS propagation takes time, and catching dependencies in advance prevents the post-move situation where everything is physically online but something still isn't working.
After the move, who you can call, and how fast they respond, matters more than most organizations plan for.
Understand Remote Hands Support
When your equipment is in someone else's facility, remote hands matter.
When your equipment is in someone else's facility, remote hands support can be what stands between a minor issue and an after-hours emergency trip.
In a cloud environment, a provider handles the physical layer for you. In colocation, you own the hardware -- which means when something needs physical attention, either you go there or someone does it on your behalf. That's remote hands.
Before committing to a provider, ask: Is support available 24/7? Are emergency reboots included? Can technicians assist with drive replacements or basic troubleshooting? What are the guaranteed response times, and are there additional fees for after-hours support?
Good remote hands support doesn't just reduce emergency trips -- it gives you confidence that someone can act on your behalf when you can't be on-site.
Choose a Provider You Can Actually Work With Long-Term
The facility specs matter. The relationship matters too.
The facility specs matter. The relationship matters too.
When evaluating a colocation provider, look for responsive support, clear escalation paths, transparent pricing without surprise overage fees, experienced technical staff, local accessibility, room for growth down the road, and a proven operational history.
A colocation facility isn't just a place to store equipment. It's infrastructure your business depends on. The right provider should feel like an extension of your team -- not just a landlord collecting a monthly rack fee.
Final Thoughts
No two colocation migrations are exactly alike, but the same principle applies to nearly all of them: preparation reduces risk.
Organizations that experience the smoothest transitions typically spend the most time documenting dependencies, validating backups, coordinating connectivity changes, and communicating expectations before the move begins.
The physical relocation may only take a day or two. The planning behind it often determines whether the migration feels routine or becomes an extended troubleshooting exercise.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
Key Takeaways
- Dwell time — how long attackers stay undetected after gaining access to systems — rose from 11 to 14 days in 2026 (Google’s M-Trends 2026 report).
- After a breach is discovered, remediation now takes an average of 43 days (Verizon DBIR 2026).
- Antivirus catches known threats. It wasn’t built to detect behavioral anomalies, lateral movement, or credential-based attacks.
- Managed EDR combines continuous endpoint monitoring with a 24/7 human SOC team that investigates and responds — not just detects.
- When a threat hit one of our clients’ endpoints, DataYard and Huntress had it contained and resolved in 52 minutes.
Why Cybersecurity Matters More Right Now
The cyber threat landscape is shifting significantly. A few numbers from research shared during the webinar put this shift into context.
Google’s M-Trends 2026 Report found that global median dwell time rose from 11 days to 14 days. Dwell time is how long a bad actor spends inside a network after gaining access before being detected. The longer that window stays open, the more damage can occur — including data exfiltration, operational disruption, and full system compromise.
Verizon’s 2026 Data Breach Investigations Report found that remediation time increased from 32 days to 43 days. Add dwell time to remediation time and you’re looking at nearly two months of a cyberattack affecting your business.
The global average cost of a data breach was $4.4 million in 2025, up 9% from the year before, according to IBM’s Cost of a Data Breach Report.
AI is accelerating the problem. The World Economic Forum identified AI-related vulnerabilities as the fastest-growing cyber risk category. IBM’s X-Force Threat Intelligence Index 2026 reported a 44% year-over-year increase in exploitation of public-facing applications and a 49% increase in active ransomware groups. Their recommendation: shift toward threat detection and response services.
Here’s how attackers are using AI today:
- AI-generated phishing — Attackers are creating personalized, grammatically clean emails in seconds using real business context and AI. The old “look for the typos” advice doesn’t hold up anymore.
- Credential and identity abuse — Attackers are using stolen credentials combined with legitimate tools, so there’s no obvious malware signature to flag.
- Automated reconnaissance — AI helps attackers find and exploit vulnerabilities faster and at a greater scale than manual methods ever allowed.
The shift isn’t just in volume. It’s in how fast attacks move and how hard they are to detect with traditional tools.
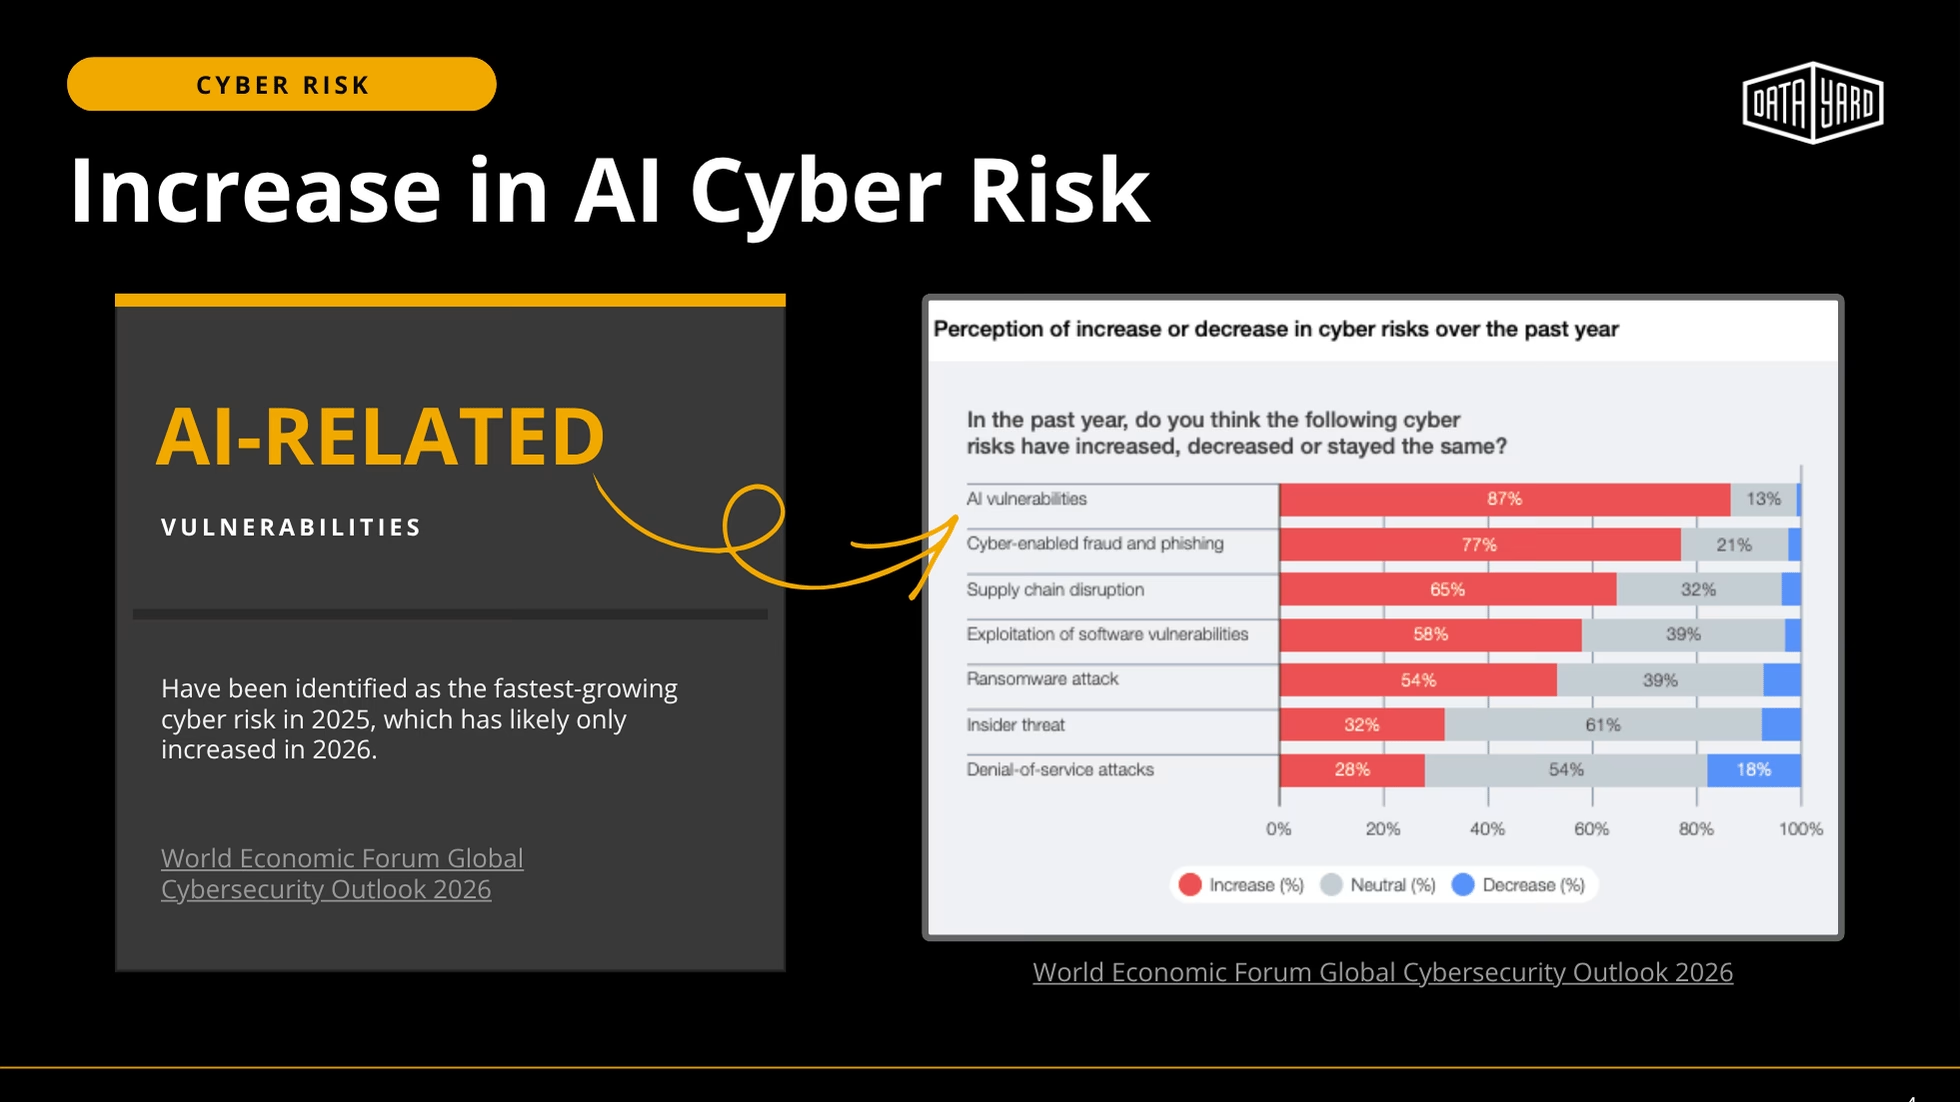
So, What Does This Mean for Your Business?
That’s a lot of stats, but taken together, these trends point to a significant shift in cybersecurity risk.
Attackers are gaining access faster, staying hidden longer, and using increasingly sophisticated techniques that often bypass traditional security tools. At the same time, organizations are taking longer to fully recover once a breach occurs.
For business leaders, the takeaway isn’t that cyberattacks are inevitable. It’s that prevention alone is no longer enough.
Traditional security tools like antivirus remain important, but they’re designed primarily to stop known threats. Today’s attacks increasingly rely on legitimate tools, stolen credentials, and behaviors that can look normal until damage is already underway.
That means organizations need the ability to quickly detect suspicious activity, investigate it, and respond before a minor incident becomes a major disruption.
The question is no longer whether your environment can block every threat. It’s how quickly you can identify and contain one when it gets through. That’s where managed EDR fits into the picture.
EDR vs. Antivirus: What’s the Difference?
Antivirus is still worth having. It detects known threats using signature matching and provides an important baseline layer of protection. But it has real limits — antivirus wasn’t designed to catch unknown threats, behavioral anomalies, or credential-based attacks that use legitimate system tools.
Managed EDR is built for what antivirus misses. EDR continuously monitors work endpoints — laptops, desktops, and servers — for suspicious behavior rather than matching against a known threat library. The “managed” part matters: instead of an alert sitting in a queue, a 24/7 SOC team investigates, contains, and helps remediate the threat.
The Managed EDR process works in four stages:
Modern attacks increasingly rely on PowerShell, Windows Management Instrumentation, and stolen credentials — tools that look legitimate right up until they don’t. That’s the gap managed EDR is built to close.
A Real Incident: Contained in 52 Minutes
One of our clients deployed managed EDR across all their endpoints as a proactive measure against lateral threat spread.
After a few months a threat was alerted on Huntress EDR. An employee unknowingly clicked a link that activated a remote monitoring and management (RMM) tool. Antivirus didn’t flag it, because it was an unknown threat operating through a legitimate tool.
Here’s what happened next:
DataYard was in contact with the client throughout. We coordinated with Huntress on remediation, kept the client informed at every step, and had the system restored in under an hour.
Without managed EDR, that threat could have moved across every connected system. Full environment cleanup from lateral spread can take weeks, and that’s before accounting for data loss, operational downtime, and the cost of rebuilding client trust.
Why DataYard Chose Huntress
Huntress was founded by former NSA contractors — people whose job was breaking into systems. When they eventually asked themselves what it would take to stop someone like them, the original Huntress EDR platform was the answer. That background shapes how the product works: it’s built around the SOC team, giving detection engineers and analysts every piece of context they need when a threat appears, not just an alert to investigate blindly.
On DataYard’s end, we spent months researching and vetting managed EDR providers before selecting Huntress. The deciding factors came down to alignment. Huntress approaches security the same way DataYard approaches client support: fast response, human accountability, and clear communication.
A few other things made them stand out as well:
- 10 million endpoints, shared threat intelligence. Huntress runs across 10 million agents globally. When a threat actor reuses infrastructure — the same hostnames, the same devices — Huntress flags it across every environment simultaneously. What hits one client informs protection for all of them.
- Internal SOC, no contractors. Huntress employs their own SOC analysts distributed around the world working different hours. Every alert is reviewed by a human before any action is taken — which is why their false positive rate stays low and their mean time to response is among the lowest in the industry.
- Built to catch what antivirus can’t. Attackers typically want the same things: get in, exfiltrate data, move laterally. Huntress watches for those behaviors — including legitimate tools being used in illegitimate ways — rather than matching against known threat signatures.
- Clear reporting after every incident. After containment, Huntress delivers a packaged incident report: what was detected, when, how, and what was done. That report is useful for cyber insurance documentation and compliance needs, not just internal review.
Huntress handles detection and SOC-level response. DataYard handles your environment, your deployment, threat remediation and direct communication when something happens. We treat your business’ security like our own.
Watch the Managed EDR Webinar Recording
On June 17, 2026, DataYard and Huntress hosted a live session on stopping cybersecurity threats using managed endpoint detection and response. Mike Beagles, DataYard’s VP of IT Operations, walked through the current threat landscape and a real 52-minute incident response. Andrew Pantaleon, Technical Account Manager at Huntress, followed with a live walkthrough of the Huntress EDR platform. Watch the full recording below.
The demo is the clearest way to see how managed EDR actually works. Watch the full recording on our webinar page.
Who Should Consider Managed EDR?
Managed EDR is most valuable for organizations that have critical systems, lean IT teams, and limited capacity to monitor and respond to threats around the clock.
If your IT team is already stretched thin, managed EDR provides continuous security monitoring and response without requiring you to build an internal security operations center.
What Managed EDR Deployment Looks Like
If you’re considering managed EDR, the deployment process is straightforward.
- Review your current security posture We begin by evaluating your existing endpoint protection, monitoring capabilities, and visibility gaps.
- Deploy Huntress agents DataYard handles deployment across your Windows, Linux, and macOS endpoints with minimal disruption to users.
- Validate visibility and coverage We confirm that endpoints are reporting correctly and that monitoring is functioning across the environment.
- Establish response workflows DataYard and Huntress work together to ensure alerts, communication paths, and remediation procedures are clearly defined.
- Begin 24/7 monitoring and response Once deployed, Huntress continuously monitors your endpoints while DataYard remains actively involved in communication, remediation, and ongoing security guidance.
If you’re not fully confident in what’s protecting your endpoints today, this is a great place to start. This free consultation includes a review of your current security posture, identification of visibility or response gaps, and honest recommendations from our team — including how quickly your organization could detect and contain a threat today.
FAQ: Managed EDR
Ready to Strengthen Your Endpoint Security?
DataYard helps organizations improve operational resilience through managed EDR, 24/7 infrastructure monitoring, endpoint protection, backup and disaster recovery, and secure cloud architecture. If you’d like to review your current security posture or explore managed EDR options, our team is happy to help.
References
- Google Cloud. M-Trends 2026: Data, Insights, and Strategies From the Frontlines.
- IBM. Cost of a Data Breach Report 2025.
- IBM. X-Force Threat Intelligence Index 2026.
- Verizon. 2026 Data Breach Investigations Report.
- World Economic Forum. Global Cybersecurity Outlook 2026 Insight Report. January 2026.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
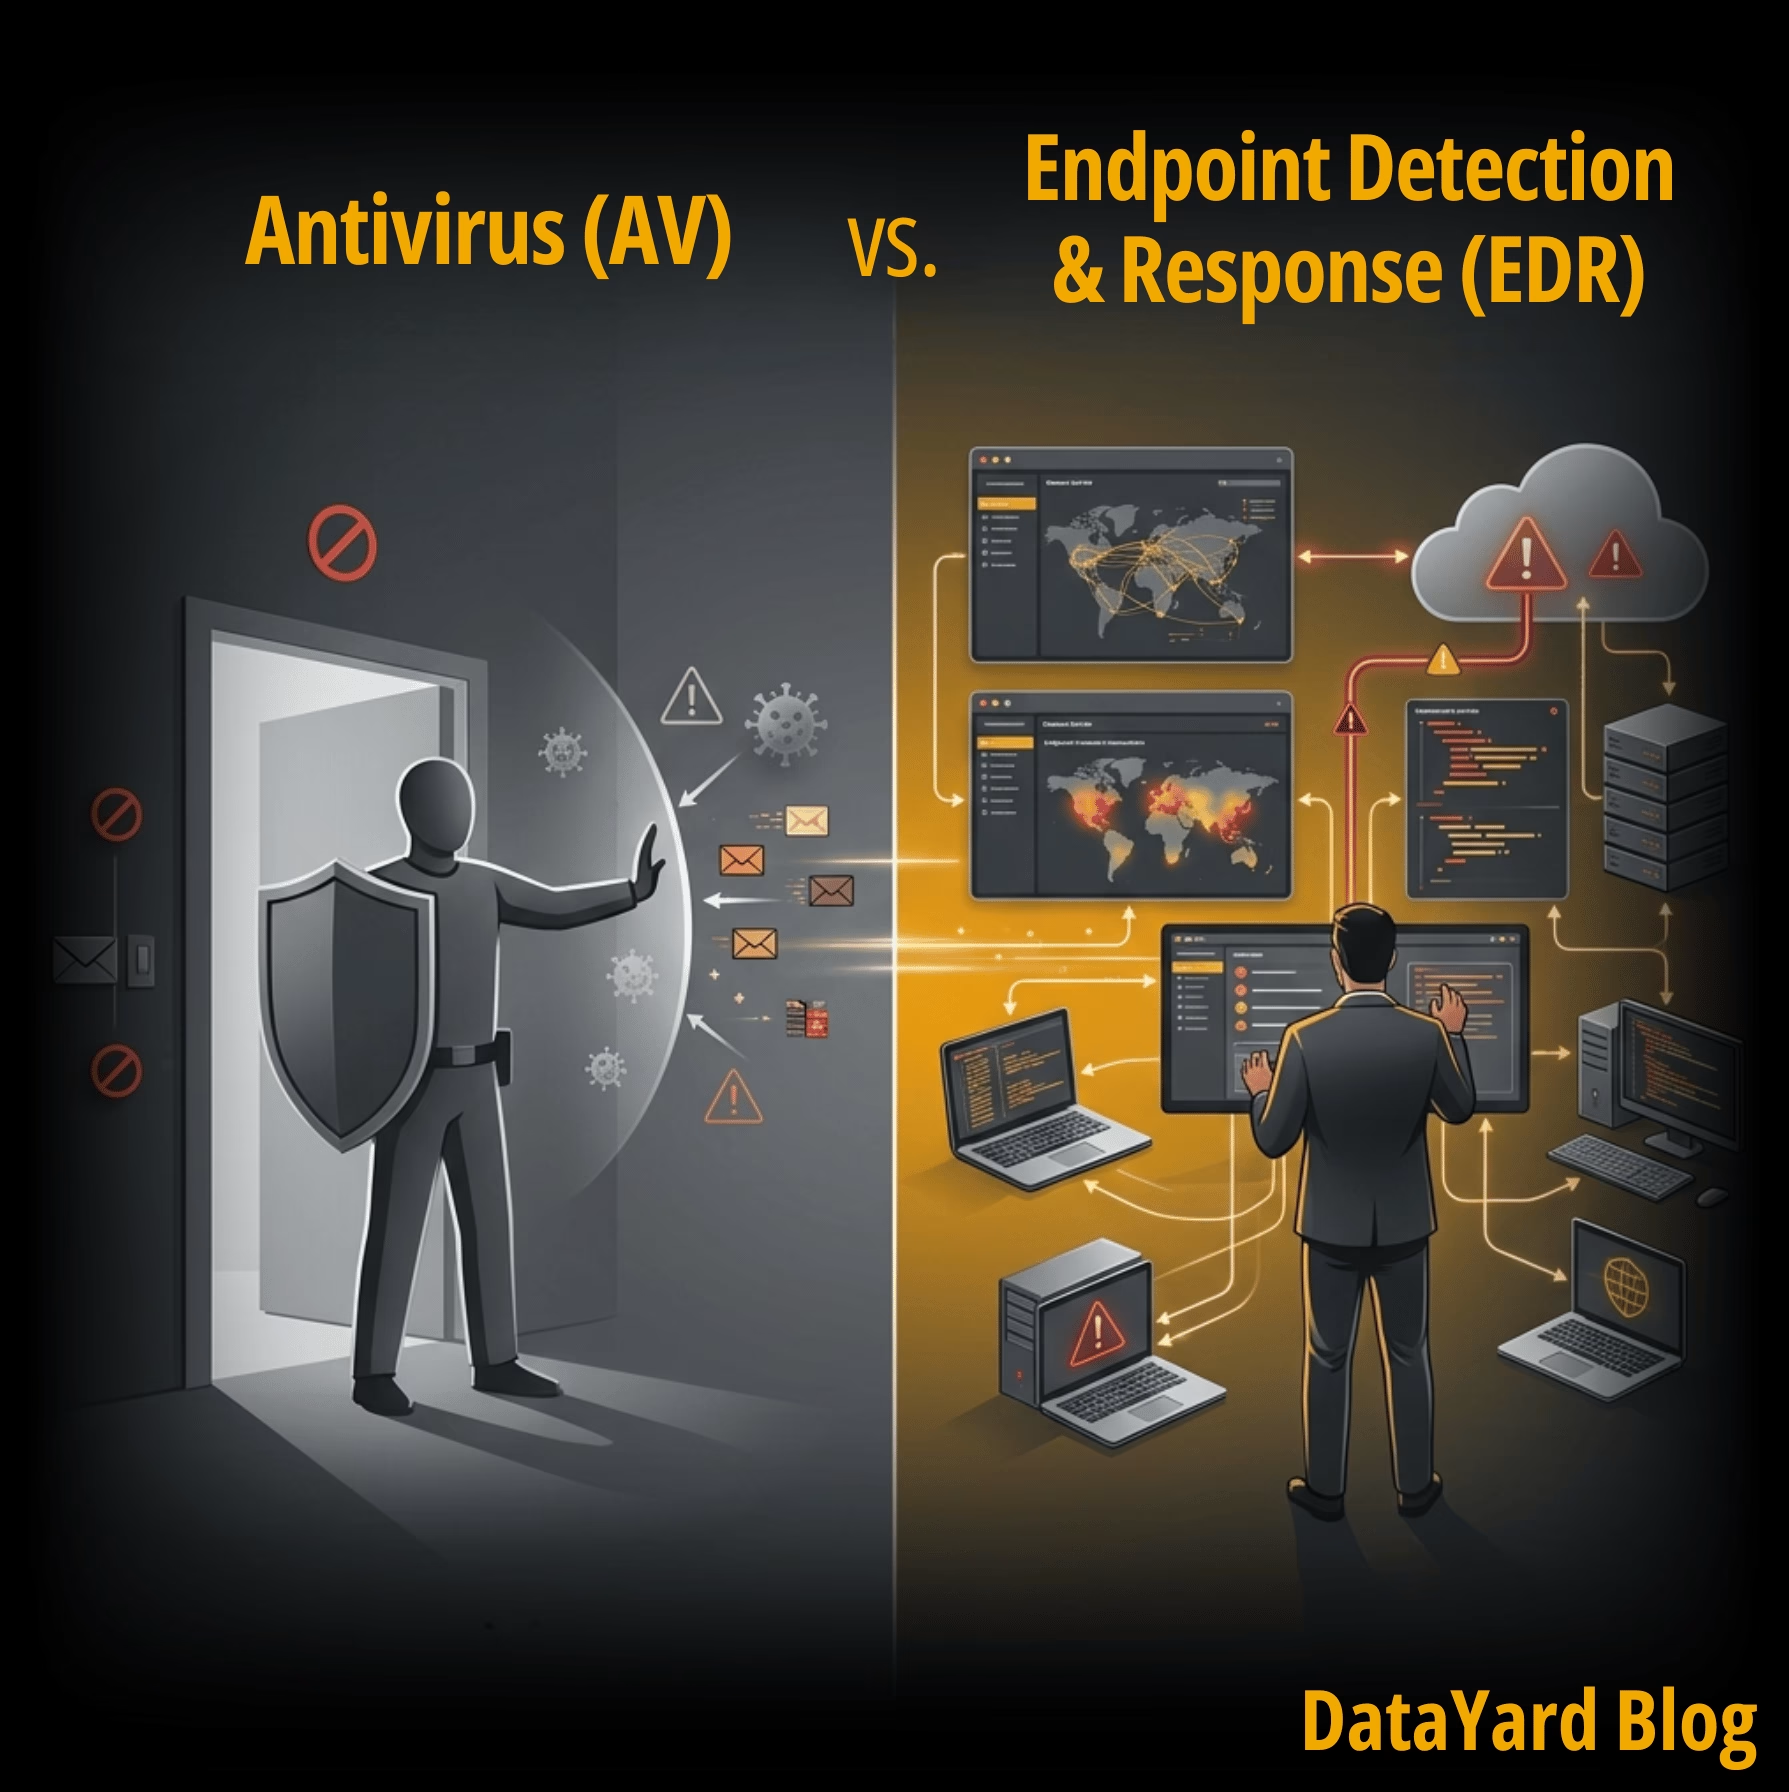
Key Takeaways
- Antivirus and EDR solve different cybersecurity problems.
- Antivirus helps block known threats before they can execute.
- EDR provides deeper visibility into suspicious endpoint activity and helps detect, investigate, and contain threats.
- Many businesses use antivirus and EDR together as part of a layered security strategy.
- Managed EDR combines endpoint monitoring with human investigation and response support.
- EDR can help organizations reduce operational disruption during cybersecurity incidents by improving visibility and response times.
What Is Antivirus Software?
Traditional antivirus (AV) software is designed to identify and block known malicious files, applications, and behaviors before they can cause damage.
Think of antivirus as a security guard checking IDs at the front door. It knows what threats look like, and it stops the ones it recognizes from getting in.
Modern antivirus platforms have come a long way from their early days and often include features like:
- Malware and ransomware protection
- Web and email scanning
- Behavioral analysis
- Automatic quarantining of suspicious files
For many businesses, antivirus remains an important first layer of defense -- one that’s effective at stopping a wide range of routine, well-known threats.
The limitation is: antivirus is most effective against threats it already recognizes. Newer, more sophisticated attacks that don’t match known signatures can pass through undetected.
What Is Endpoint Detection & Response (EDR)?
EDR goes a step further than antivirus. Rather than focusing on blocking known threats, EDR continuously monitors behavior across your endpoints -- workstations, laptops, servers, and remote employee devices -- and flags activity that looks suspicious based on users' typical working patterns, even if it doesn't match a known signature.
Going back to the security guard analogy: if antivirus is the guard checking IDs at the door, EDR is the broader security team monitoring cameras throughout the building, investigating anything that looks off, and responding when something abnormal happens -- even after someone’s already inside.
EDR platforms give organizations the ability to:
- Detect unusual or suspicious behavior in real time
- Investigate incidents quickly with full context
- Isolate affected systems before threats can spread
- Reduce lateral movement across a network
- Respond faster when something goes wrong
Fast response times matter more than many businesses realize. The window between when a threat is detected and when it’s contained can be the difference between a minor incident and days of downtime.
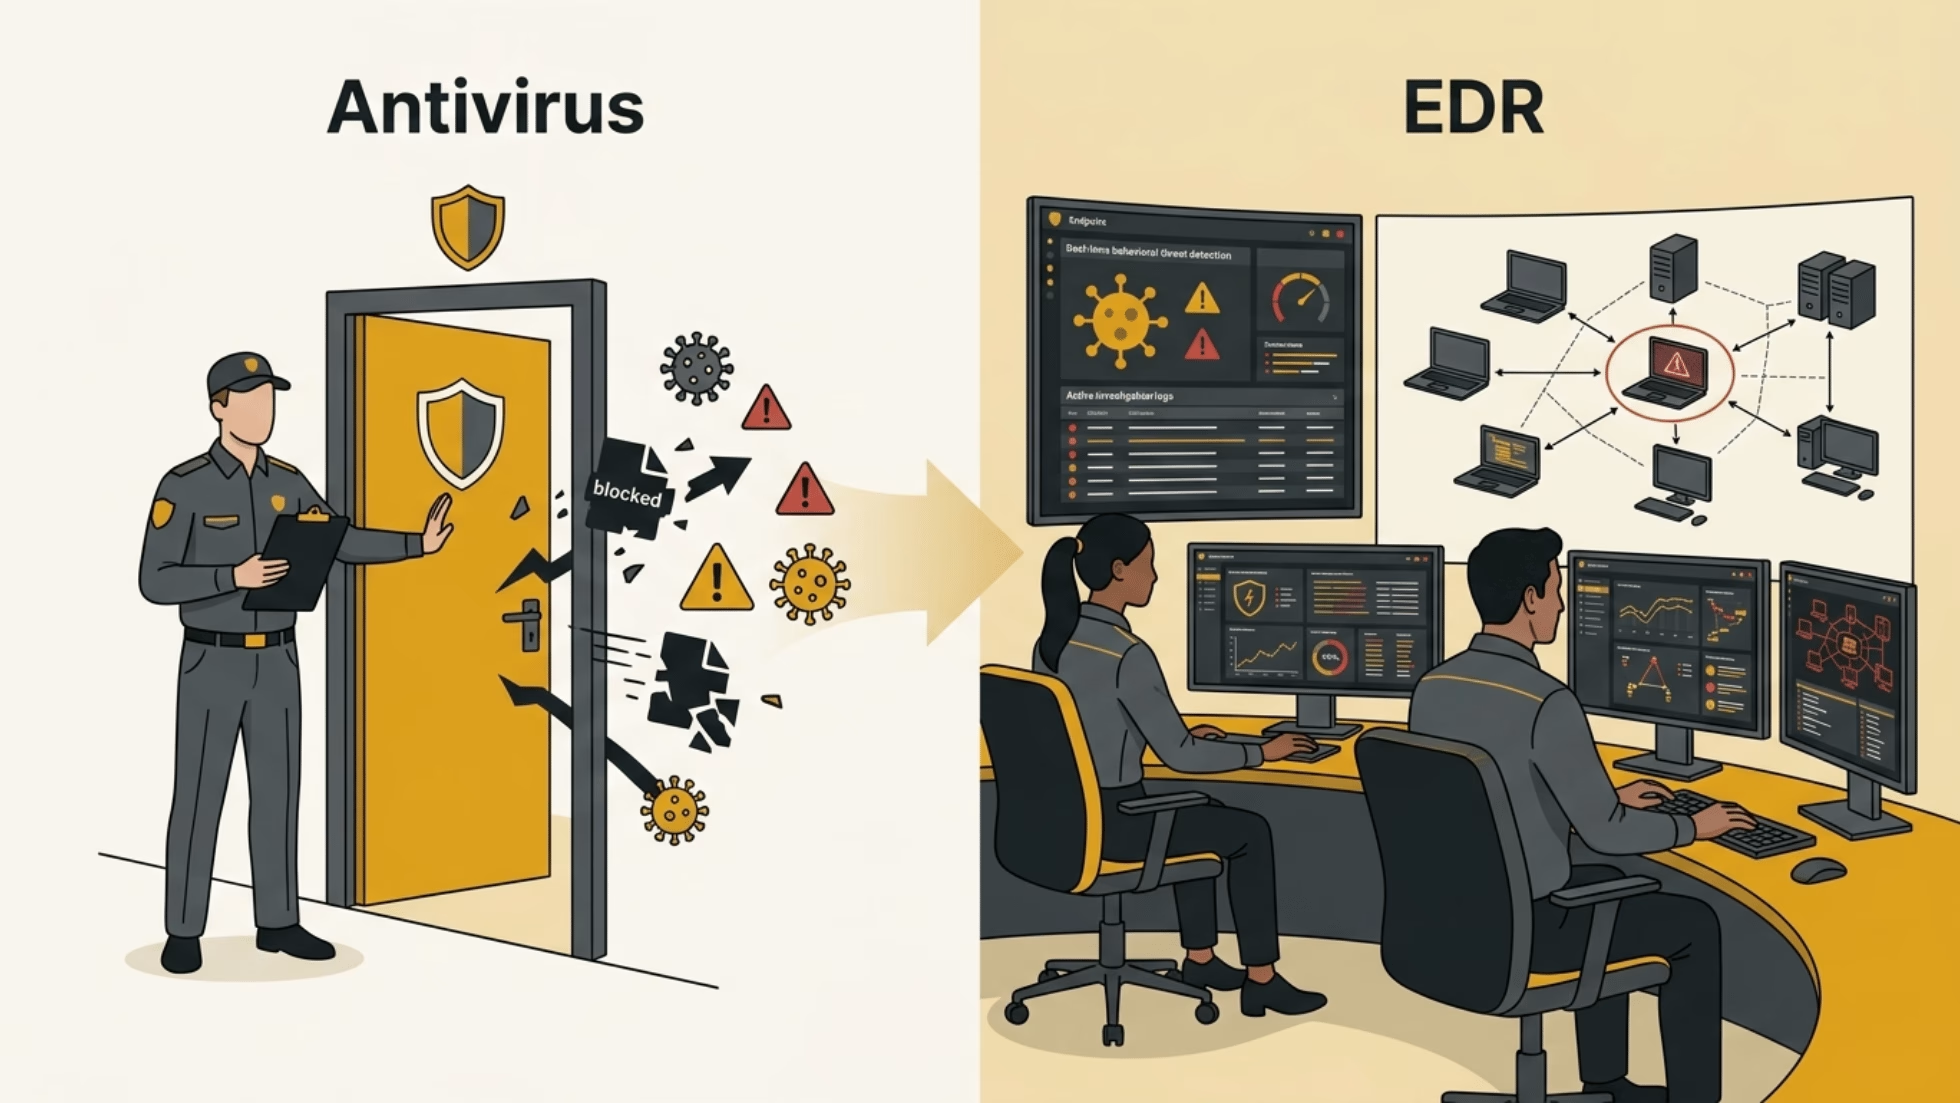
Why EDR Is Becoming More Important
Cybersecurity threats have become increasingly focused on endpoints, including the workstations, laptops, and servers your employees use every day.
According to Huntress, attackers frequently rely on legitimate administrative tools, stolen credentials, remote access software, and “living off the land” techniques that may not appear malicious to traditional antivirus software alone. These types of attacks are designed to blend in, and that’s exactly what makes them so difficult to catch with prevention-only tools.
It’s one of the main reasons EDR adoption has grown significantly in recent years. Rather than relying solely on known malware signatures, EDR helps organizations identify suspicious behaviors and investigate unusual activity that may indicate compromise.
Modern EDR platforms can also help reduce response times by:
- Alerting IT teams to suspicious activity quickly
- Providing behavioral visibility into endpoint activity
- Isolating affected devices during active incidents
- Supporting faster investigation and remediation
For businesses with remote employees or operationally-critical systems, that improved speed and visibility can make a meaningful difference in how disruptive a security incident ends up being.
Huntress reports that 89% of users agree that Managed EDR stopped a threat that would have otherwise significantly impacted their business -- a strong indicator of why managed detection is becoming a go-to addition for lean IT teams.
EDR vs. Antivirus: Key Differences
While both tools improve endpoint security, they work differently and serve different purposes.
Antivirus focuses on prevention. It’s built to block known malicious files and activity before they execute -- quietly, automatically, and with minimal input needed from your team.
EDR focuses on visibility and response. It’s built to a) catch what slips past those initial prevention layers, b) give your team the context to understand what happened, and c) provide the tools to contain it and remediate the issue quickly.
Antivirus is largely automated. It runs in the background and handles routine threats without a lot of end-user investigation. As long as your AV service is installed and kept up-to-date, there isn't much involvement required from IT.
EDR provides deeper investigation capability. EDR platforms typically include threat timelines, behavioral monitoring, forensic visibility, and containment features -- tools that help IT teams understand the full scope of an incident, not just an alert that "something happened".
Neither tool is a complete security strategy on its own. Together, they cover a much broader range of threats.
| Feature | Antivirus | EDR |
|---|---|---|
| Blocks known malware | Yes | Yes |
| Behavioral monitoring | Limited | Extensive |
| Threat investigation tools | Minimal | Advanced |
| Endpoint isolation | Usually No | Yes |
| Detects suspicious activity | Limited | Yes |
| Incident response support | Minimal | Strong |
| Visibility into endpoint activity | Limited | Detailed |
| Best for | Prevention | Detection & Response |
Not sure if your current security stack has the right coverage? DataYard can help you assess where antivirus and EDR fit into your environment. Contact us or explore DataYard’s cybersecurity services.
Why Many Businesses Use Both
Cybersecurity rarely comes down to a single tool. Most strong security setups are built in layers, and antivirus and EDR are designed to cover different parts of that stack:
- Prevention -- Stopping known threats before they execute (Antivirus)
- Detection -- Identifying suspicious activity that bypasses prevention (EDR)
- Investigation -- Understanding what happened and how far it spread (EDR)
- Response -- Containing the threat and limiting damage (EDR)
In many cases, antivirus handles routine threats before they ever become incidents. But when something more sophisticated slips past antivirus and firewall protections -- and it does happen -- EDR provides the visibility needed to catch it quickly and limit the damage.
For organizations with remote employees, growing infrastructure, or operationally critical systems, that additional visibility isn’t a nice-to-have; it's what separates a contained incident from a serious disruption.
What Is Managed EDR?
EDR technology provides powerful visibility and response capabilities, but the platform still requires someone to monitor it, investigate alerts, and make decisions when suspicious activity occurs.
That’s where managed EDR comes in.
Managed Endpoint Detection & Response combines EDR technology with active human monitoring and response support. Instead of relying entirely on an internal IT team to review every alert, organizations gain access to experienced security professionals who help investigate suspicious activity and respond to incidents faster.
DataYard partners with Huntress to provide managed EDR services that help organizations:
- Monitor endpoint activity continuously
- Investigate suspicious behavior with expert support from Huntress' SOC
- Respond faster to active threats
- Reduce alert fatigue for internal IT teams
- Improve visibility across remote and hybrid environments
For many small and midsize businesses, managed EDR provides access to advanced endpoint security capabilities without needing their own internal security operations center (SOC).
This can be especially valuable for:
- Manufacturers with operationally critical systems
- Professional service firms handling sensitive client data
- Organizations with remote or hybrid employees
- Growing businesses with limited internal IT resources
Rather than deploying security software and hoping for the best, managed EDR adds an additional layer of human visibility, expertise, and expedited response when it matters most.
DataYard offers Managed EDR through our partnership with Huntress. If your organization is looking to improve endpoint visibility without adding to your internal team’s workload, we’re happy to walk through what that looks like for your specific environment. Contact us to start the conversation.
How EDR Saved One of Our Clients
Earlier this year, DataYard responded to an incident that shows exactly why this matters.
Our team received an alert from Huntress — our managed EDR partner — flagging suspicious activity on a client's workstation. A team member had unknowingly downloaded a file that turned out to be a Remote Monitoring & Management (RMM) tool — the kind attackers use to gain unauthorized access to a system and move laterally through a network.
The client's antivirus software didn't catch it. The file didn't match any known malicious signature.
But EDR did. It detected the unusual behavior, isolated the affected device, and the Huntress and DataYard teams had everything contained and resolved within the hour. Without EDR, that same threat could have spread across the client's entire network — potentially causing days (or weeks!) of downtime.
We walked through this incident in detail during a past EDR webinar -- including what triggered the alert, how we responded, and what was prevented.
EDR Benefits for All Growing Businesses
For any growing organization, a cybersecurity incident isn’t just an IT problem -- it’s an operational one. Downtime affects production. Data exposure affects client relationships. Recovery takes time your team doesn’t have.
EDR is especially valuable in environments where:
- Downtime has real consequences for production or revenue
- Remote work expands the number of endpoints that need monitoring
- Small internal IT teams are managing large or complex environments
- Legacy systems create blind spots that traditional tools miss
- Sensitive client or operational data needs to be protected
The goal of EDR isn’t just stopping malware. It’s giving your team the visibility and response capability to handle incidents faster, and with less disruption, when they happen.
Watch the EDR Webinar Replay
Our live webinar has concluded, but you can still watch the full presentation on demand.
How to Stop Cybersecurity Threats with Endpoint Detection & Response (EDR)
▶ Webinar Recording Available On Demand
🛡 Real-World Incident Response Walkthrough
💻 Free to Watch
In this webinar, DataYard’s VP of Operations Mike Beagles walks through a real cybersecurity incident involving EDR detection and containment, including what triggered the alert, how the response unfolded, and what was prevented.
You’ll also see a live demonstration from Andrew Pantaleon, Technical Account Manager at Huntress, showing how modern EDR solutions help organizations detect, investigate, and respond to threats in real time.
Read the webinar recap and watch the complete recording to learn how EDR can strengthen your organization’s cybersecurity posture.
Final Thoughts
The EDR vs. antivirus question isn’t really an either-or decision for most businesses. Antivirus remains a valuable first layer of protection. EDR adds the visibility and response capability that modern threat environments increasingly require.
When used together, they cover more ground -- from blocking routine threats to detecting, investigating, and containing the ones that don’t look like anything you’ve seen before. As ransomware and endpoint-based attacks continue evolving, many organizations are adding managed EDR services alongside traditional antivirus protection.
If you’d like to talk through what endpoint security looks like for your specific environment, contact the DataYard team. We’re happy to have a conversation about where you stand and what makes sense to add to your security stack.
Ready to Strengthen Your Endpoint Security?
DataYard helps organizations improve operational resilience through managed EDR, 24/7 infrastructure monitoring, patch management, endpoint protection, backup and disaster recovery, and secure cloud architecture. If you’d like to review your current security posture or explore managed EDR options, our team is always happy to help.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup
Key Takeaways
- Claude Mythos Preview was announced April 7, 2026.
- Reports surrounding Anthropic's "Mythos" research are still emerging publicly.
- Access is currently limited to large organizations through Anthropic's Project Glasswing.
- Identifying a vulnerability is different from reliably exploiting hardened systems.
- Businesses already operate in a world where unknown vulnerabilities exist.
- The fundamentals of good security haven't changed: monitor, patch, detect, respond.
What We Know So Far About Anthropic's Claude Mythos
On April 7, 2026, Anthropic announced Claude Mythos Preview as a new general-purpose AI model that Anthropic says demonstrated advanced cybersecurity research capabilities during internal testing. Specifically, they claim Mythos can identify previously unknown zero-day vulnerabilities in widely used software, including major operating systems and browsers.
Access to Mythos is currently limited to a small group of large technology and security organizations through what Anthropic calls Project Glasswing. Participating organizations include Google, Amazon, Microsoft, AWS, Cisco, The Linux Foundation, and CrowdStrike. Anthropic says the goal is to evaluate whether AI-assisted vulnerability research can help identify security flaws before attackers discover them. The company has also stated that additional findings and technical details from the project may be released publicly after an initial 90-day evaluation period.
So what should businesses take away from all of this? Here's what security researchers are debating, what remains uncertain, and what organizations should realistically focus on right now.
What Security Researchers Are Debating
Much of the attention around AI-assisted cybersecurity focuses on whether models could accelerate vulnerability discovery faster than defenders can respond. That concern is understandable. However, many security professionals have also urged caution about overstating current capabilities.
Security researcher Bruce Schneier acknowledged that Mythos's capabilities are significant, but raised a specific concern about what Anthropic's data doesn't show: the false positive rate on unfiltered output. Anthropic reported 89% severity agreement between the model and human security contractors, but that figure comes from a curated sample of findings, not a full-run distribution. As Schneier noted, AI systems that detect nearly every real bug can also generate plausible-sounding vulnerabilities in already-patched or correct code. A tool that produces high-confidence false positives at scale may add operational burden rather than reduce it.
Other evaluations -- including one conducted by the UK government's AI Security Institute (AISI) -- suggested that while advanced AI systems may improve performance in controlled research environments, it remains unclear how effective they would be against well-defended systems.
There is an important technical distinction between identifying a vulnerability and successfully compromising a hardened environment. Finding a flaw is not the same thing as reliably exploiting it against systems protected by layered security controls, monitoring, endpoint protection, and active response teams. Skilled human review remains part of the equation.
Why This Matters for Businesses
Most businesses already operate in an environment where unknown vulnerabilities exist. The reality is that software flaws are sometimes discovered long before patches become publicly available.
What makes AI-assisted vulnerability research noteworthy is the possibility that discovery timelines could accelerate. If vulnerabilities can be identified more quickly, the window between discovery, active exploitation attempts, and vendor patch releases could become smaller.
For organizations without large internal security teams, that increases the importance of strong operational security practices. Monitoring systems closely, reducing unnecessary exposure, deploying patches quickly, and responding rapidly to suspicious activity all become even more important when threat timelines move faster.
That is especially relevant for organizations managing critical infrastructure, manufacturing systems, financial data, or customer-facing applications where downtime and disruption carry real business consequences.
The challenge for most businesses is not discovering vulnerabilities first. It is maintaining visibility into their environments and responding effectively as threats emerge.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup

Key Takeaways
- Many manufacturing migrations run into problems because of undocumented dependencies and system complexity.
- Start with low-risk workloads. Avoid beginning with production-critical systems.
- Establish performance baselines before the migration so results can be measured afterward.
- The migration window introduces additional security risk, so planning ahead matters.
- Most manufacturers end up with some form of hybrid architecture.
Cloud Migrations for Manufacturing Companies
Manufacturing companies often approach cloud migrations differently than most industries, and for good reason. In most environments, a poorly executed migration creates inconvenience. In manufacturing, it can stop production.
A single overlooked dependency, such as a reporting tool tied to a production database, can cause unexpected downtime. Not just because the system is complex, but because the connections weren't fully understood before the move.
This guide outlines a practical cloud migration checklist designed specifically for manufacturing environments, where uptime and operational continuity are critical.
Why This Guide Is Different
Most cloud migration content is written for software companies whose environments are designed to change quickly. Manufacturing environments are not.
This guide focuses on the systems, dependencies, and constraints that manufacturing IT teams deal with every day, including legacy ERP integrations, operational and information technology boundaries, production schedules that do not bend for migration timelines, and the real cost of unplanned downtime.
Before You Start...Not Everything Belongs in the Cloud
One of the most common mistakes to make during a virtualization project is assuming everything should move. In manufacturing environments, that approach rarely works.
Some systems benefit from being moved to a virtualized or private cloud environment, particularly those that need off-site resilience, flexible compute, or relief from aging on-premises hardware. Others, particularly those tied to production equipment or requiring very low latency, are sometimes better kept on-premises.
In practice, most manufacturers adopt a hybrid architecture, combining private cloud, public cloud, and on-prem systems. This is not a fallback. It's often the most practical architecture for balancing performance, reliability, and flexibility.
Many organizations operate across a mix of cloud and on-premises environments, according to Flexera's 2026 State of the Cloud Report.
Need a secure environment for systems that shouldn't move to the cloud? Explore flexible colocation options.

Why Manufacturing Cloud Migrations Are Different
Manufacturing environments tend to evolve over time rather than being designed from scratch. ERP platforms connect to MES systems, which connect to production data, reporting, and scheduling. That data feeds supplier coordination and downstream processes. Some of those connections are documented. Others only become visible when something breaks.
Production systems are expected to operate continuously. Changes must align with maintenance windows, staffing, and delivery commitments, which limits when and how migrations can occur.
The biggest challenge is often unrelated to speed, but rather to understanding how systems interact before making changes.
Cloud Migration Checklist for Manufacturing Companies: Step-by-Step
A successful migration is not a single event. It's a sequence of controlled steps.

The checklist chart below provides a quick overview of the 10 steps manufacturers can take to migrate to the cloud. Below, we break down each step with a focus on maintaining operational continuity.
Checklist Quick Overview
← Scroll to see full table →
| # | Step | What You're Doing |
|---|---|---|
| 1 | Build a System Inventory | Document all systems and integrations |
| 2 | Categorize Inventory | Identify what is highest priority for minimal downtime |
| 3 | Map Dependencies | Trace how systems connect |
| 4 | Establish Baselines | Measure current performance |
| 5 | Assess Readiness | Identify prep requirements |
| 6 | Plan Security | Define controls and monitoring |
| 7 | Design Recovery | Define RTO/RPO and test restores |
| 8 | Choose Strategy | Assign migration approach per system |
| 9 | Pilot Migration | Test with low-risk workloads |
| 10 | Execute & Monitor | Controlled production migration |
Understand What You Have
Create a complete inventory before making any changes.
Start with a full inventory of your environment. Systems often get added over time in manufacturing, and documentation doesn't always keep up.
Focus on identifying:
- Core applications and databases (ERP, MES, reporting tools)
- Infrastructure: physical servers, virtual machines, disaster recovery systems
- Network components, firewalls, and integration points
- Automated processes, scheduled jobs, and batch file transfers
The goal is not perfection. It's reducing surprises later. This level of detail is also valuable if you choose to work with a cloud migration professional. Accurate documentation helps determine the order of migration and reduces the risk of issues during execution.
Once you understand what exists in your environment, the next step is determining what matters most.
Categorize Your Inventory
Identify which systems can and cannot tolerate downtime.
Categorize your systems into tiers based on their tolerance for downtime. For example:
- Tier 1: ERP, MES, production control. These cannot go down during production hours.
- Tier 2: Scheduling, reporting, inventory. Disruption is painful but recoverable.
- Tier 3: Non-critical systems. Good candidates for early migration.
Start with your non-critical systems first (Tier 3). By the time you reach Tier 1, the process should feel proven, not experimental.
After categorizing systems by criticality, the next step is understanding how they connect.
Map Dependencies
Document how systems connect to each other before moving anything.
In manufacturing environments, systems are rarely isolated. Missing a single dependency between systems is one of the most common causes of migration problems. Further, these problems often appear hours after migration, not necessarily during it.
For each system, document:
- API connections and data flows
- File transfers and shared storage paths
- Authentication dependencies (Active Directory, SSO, LDAP)
- OT/IT integration points, where production systems meet business systems
- Vendor or supplier connections that touch internal systems
- Other undocumented or less visible connections between systems

A Note on Hidden Dependencies
The dependencies that cause the most trouble are often the ones that were never documented. These can include dependencies added years ago by someone who has since moved on, automated reports that run overnight, file syncs between systems that are no longer actively monitored, or custom integrations built for a specific use case.
Plan time to identify these before migration begins, not during it.
Establish Performance Baselines
Measure current performance so you can validate results after migration.
Before making changes, understand how your systems perform today. Response times, uptime, query performance, behavior under production load.
Without a baseline, you can't determine whether the migration improved performance or introduced new issues. Baselines also become your go/no-go criteria during the pilot phase.
Assess Readiness
Determine which systems require preparation before migration.
Not every system is ready to move without preparation. Common readiness gaps in manufacturing environments include:
- Operating systems or databases that are end-of-life.
- Custom applications with no vendor support or documentation.
- Latency-sensitive systems that need testing in the new environment.
- Licensing that doesn't transfer to virtualized infrastructure.
Identifying these issues during planning (rather than during execution) prevents delays when you're in the middle of a production maintenance window.
Plan Security Before Migration
Define security controls before systems exist in multiple environments.
During migration, systems temporarily exist in multiple environments and data is actively moving. This increases exposure.
Manufacturing is a leading target for cyberattacks, according to the IBM X-Force Threat Intelligence Index, making the migration window especially sensitive.
Before the first system moves, define:
- Network segmentation
- Access controls
- Encryption standards
- Monitoring and alerting configuration

Quick Tip: Security should be designed into the migration, not added afterward.
Plan for Recovery
Ensure systems can be restored quickly if something goes wrong.
Even well-planned migrations encounter issues. The difference between a minor incident and an operational disruption is recovery planning.
For each system tier, define:
- Recovery Time Objective (RTO) How long can this system be down before it impacts production?
- Recovery Point Objective (RPO) How much data loss is acceptable? For most production systems, the answer is very little, which means backup frequency and storage location matter.
- Backup strategy Where are backups stored, and have restores been tested?
With planning complete, the focus shifts to reducing risk during execution.
Choose a Migration Strategy
Assign the right approach to each workload.
Not every system gets migrated the same way. Assign an approach to each workload before execution begins. These are the four approaches commonly used in manufacturing environments:
← Scroll to see full table →
| Approach | What It Means | Best For |
|---|---|---|
| Re-host | Move the system as-is to the new hosting environment | Systems that work fine, but just need to move off aging hardware |
| Re-platform | Make targeted improvements during the move to the new environment | Systems needing minor modernization without a full rebuild |
| Retain | Keep in the current on-prem environment | Production-critical, low-latency systems not ready to move |
| Retire | Decommission systems no longer needed | Legacy tools with no active users or replaceable functionality |
Pilot Before Production
Validate the process using low-risk systems first.
Before touching any Tier 1 systems, validate your process with Tier 3 workloads. Your pilot should confirm:
- Performance meets or exceeds baseline expectations.
- Integrations function correctly in the new environment.
- Backup and recovery processes work as documented.
- Security controls are active and correctly configured.
- Your team can execute the runbook under pressure.
By the time you reach production systems, the migration process should feel routine.
Execute and Monitor
Run a controlled migration with a tested rollback plan.
Execution discipline is critical during production migration. A structured runbook should include:
- Step-by-step tasks with clear ownership for each.
- Go/no-go checkpoints at defined milestones.
- A tested rollback plan, not theoretical.
- A communication plan for operations, leadership, and affected vendors and clients.
After migration, plan for a stabilization period of several weeks. Validate performance against baselines, tune the environment, and handle issues that only appear under real production load. Ongoing monitoring and alerting after the migration help identify and resolve issues before they impact operations.
Want a printable version of this checklist? Download a fillable worksheet to map your systems, identify dependencies, and plan your migration step-by-step.
Download Resource Download the Cloud Migration Checklist Worksheet →What This Looks Like in Practice
← Scroll to see full table →
Most successful manufacturing migrations follow a phased approach. Rushing the early phases can be the cause of multiple migration failures.
| Phase | Focus |
|---|---|
| Discovery | Inventory and dependency mapping |
| Planning | Strategy, security design, rollback planning |
| Pilot | Testing and validation with low-risk workloads |
| Production | Controlled rollout, phased by system tier |
| Stabilization | Monitoring, optimization, and issue resolution |
Final Thoughts on Manufacturing Cloud Migration

Cloud migration in manufacturing isn't about moving everything. It's about understanding your environment, placing each system where it performs best, and executing those changes without extended disruptions to production.
The most successful migrations aren't the fastest, they're the most deliberate. They prioritize:
- Visibility into system dependencies
- Controlled testing before production impact
- Clearly defined and validated recovery plans
For many manufacturers, the end result isn't fully cloud-based. It's a well-architected hybrid environment designed to support both operational stability and future growth.
Planning a Cloud Migration but Want a Second Perspective?
If you're preparing for a move, our team can help you evaluate your environment, identify risks, and support the migration process from planning through execution.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup

Why Manufacturing Runs on Legacy Systems (And Why That's Not Always a Bad Thing)
Manufacturing environments prioritize stability above almost everything else. Systems that control machinery, production schedules, inventory management, or supplier coordination are rarely replaced quickly because disruption carries real operational risk.
When a system controls your production line, it usually stays in place until there is a reason to change it.
Most manufacturers operate a combination of:
- Legacy ERP systems
- Manufacturing Execution Systems (MES)
- Custom internal applications
- On-premise SQL databases
- File servers supporting production and engineering teams
The physical hardware running these systems often remains in place past its prime because replacing them outright can be expensive and disruptive. The problem is what happens when the infrastructure supporting them starts to age out.
The Real Problem: What Happens When Infrastructure Gets Old
As servers move past their recommended lifecycle, the risk of disruption increases — often in ways that aren't obvious until something breaks. It's important to understand these risks so you can prepare before they impact operations.
Here are four risks that come with aging manufacturing infrastructure:
Hardware Failure Risk
Most enterprise servers are designed for a lifecycle of 3–5 years according to a variety of hardware manufacturers, though real-world deployments often run longer. Industry research from Park Place Technologies estimates typical lifespans of around 6 years for rack servers and up to 10 years for integrated systems.
As systems age beyond these ranges, hardware failures become more likely, and replacement components become harder to obtain. Unexpected failures can bring critical applications offline, delay recovery efforts, and create cascading issues across dependent systems.
When that happens in a manufacturing environment, the consequences quickly move from technical problems to operational disruption.
Downtime and Production Disruption
When critical systems go down, the resulting downtime can become costly. A Siemens study estimated that "the cost for an average large plant in the sectors we surveyed is now $253 million a year."
Even small interruptions can delay shipments, disrupt production schedules, and impact customer commitments. At the same time, aging infrastructure can create gaps in visibility and protection that expose businesses to modern cybersecurity threats.
Security Vulnerabilities
Manufacturing has become one of the most frequently targeted sectors for cyberattacks.
Older infrastructure often lacks modern monitoring, automated patching, network segmentation, and advanced threat detection. Even when legacy systems continue running, they often require increased effort and additional resources to maintain.
Rising Maintenance Costs
As systems age, organizations spend increasing time maintaining them. Replacement parts, manual management processes, and emergency repairs can gradually increase operational costs. In many environments, maintaining legacy infrastructure eventually becomes more expensive than modernizing it.
At that point, businesses are not just maintaining infrastructure -- they're investing more each year to sustain systems that provide less reliability and fewer capabilities than modern alternatives.
To better understand the impact of modernization, it helps to compare legacy infrastructure with a modernized environment. The differences often appear in reliability, security, backup capabilities, and scalability.
Keep in mind, modernization doesn't always mean a full replacement. For many organizations, it involves a hybrid approach -- combining existing infrastructure with private or public cloud resources to improve performance, resilience, and flexibility.
The table below highlights how common risks in legacy infrastructure translate into practical benefits when environments are modernized.
← Scroll to see full table →
| Area | Legacy Infrastructure Risk | Modernized Environment Benefit |
|---|---|---|
| Hardware | Aging servers prone to failure | Virtualized infrastructure with redundancy |
| Security | Limited monitoring and end-of-life security updates | Continuous monitoring and automated updates |
| Backup | Manual or untested recovery processes | Automated backups with tested recovery |
| Scalability | Fixed hardware capacity | Scalability options in the cloud |
DataYard helps manufacturers move forward — with private cloud environments designed for organizations that can't afford downtime. Proven since 1995.
Let's Talk Shop →Signs Your Manufacturing Systems Need Legacy System Modernization
Many legacy systems remain stable for years. The challenge is recognizing when the infrastructure supporting those systems begins creating operational risk.
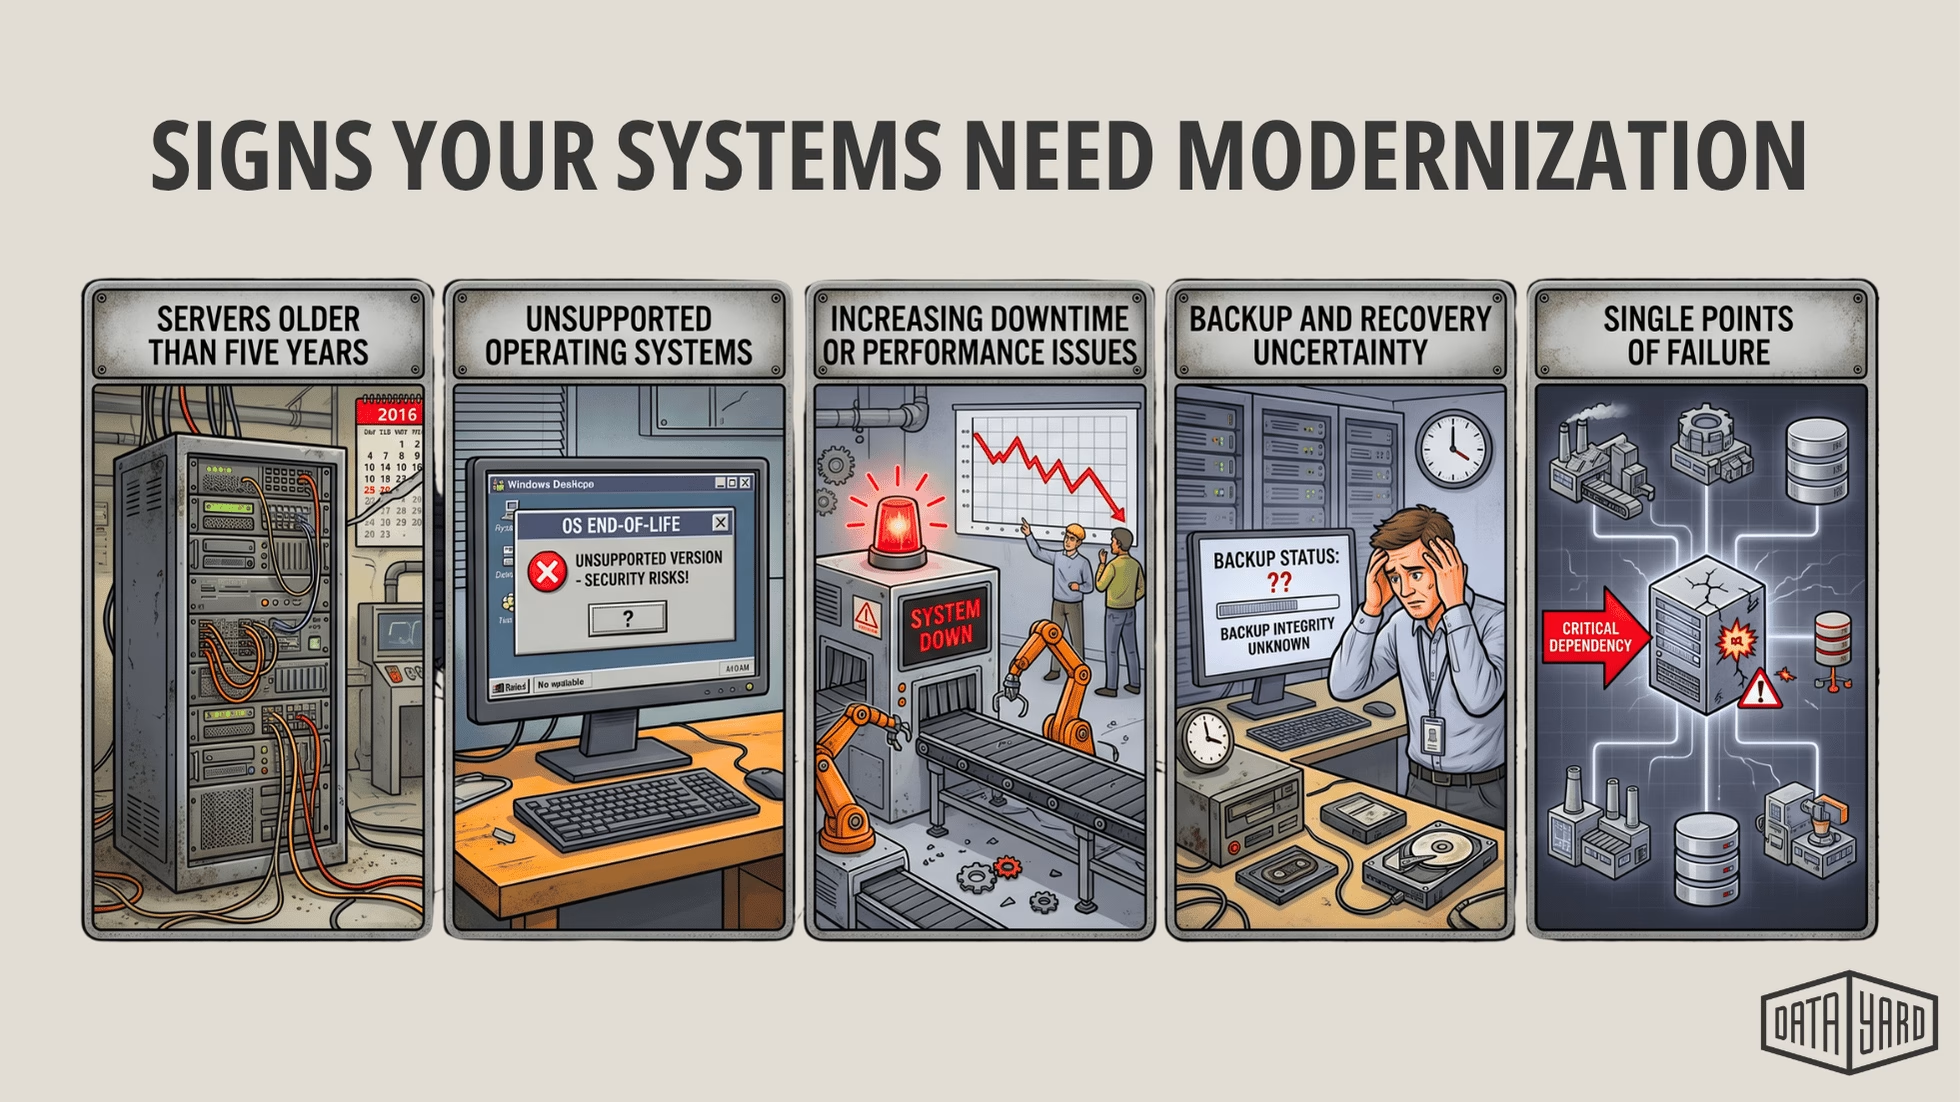
Here are the most common warning signs we see when working with manufacturers in the region.
Servers Older Than Five Years
Most enterprise hardware is designed for a lifecycle of 3–5 years. Servers older than that may still function, but the failure risk increases significantly. When critical systems depend on aging hardware, a single failure can suddenly disrupt production.
Unsupported Operating Systems
Operating systems and databases eventually fall out of vendor support. Once this happens, security patches stop, compatibility issues increase, and vendor support becomes limited. Running unsupported infrastructure increases exposure to ransomware and security vulnerabilities.
Increasing Downtime or Performance Issues
Aging infrastructure often begins showing symptoms such as slower system performance, intermittent outages, storage limitations or other resource bottlenecks, and network latency. These issues can quietly impact production efficiency long before a major outage occurs.
Backup and Recovery Uncertainty
Many organizations assume their backup systems will work during a crisis. However, during modernization assessments, it is common to discover that backups have never been fully tested, restore processes take far longer than expected, and recovery procedures are undocumented. Reliable disaster recovery requires modern backup infrastructure and regular testing.
Single Points of Failure
Older environments frequently contain infrastructure that was never designed with redundancy — a single server supporting ERP or MES workloads, a single storage array holding production data, or one network device connecting multiple facilities. Modern infrastructure introduces redundancy and failover protections to reduce operational risk.
Noticing you're checking a few of those boxes? Get a straight answer from our team before it becomes a bigger issue.
Most Commonly Modernized Manufacturing Systems
Modernization efforts typically focus on the infrastructure supporting a handful of mission-critical systems. These are the platforms that directly impact production, visibility, and day-to-day operations.
Below is a breakdown of common systems, and why they're often modernized:
← Scroll to see full table →
| System | Why It Gets Modernized |
|---|---|
| ERP Systems | Central production coordination |
| MES Platforms | Real-time manufacturing workflows |
| SQL Production Databases | Growing operational data |
| Engineering File Servers | CAD files and operational documentation |
| Custom Internal Applications | Production reporting and workflow tools |
Knowing what to modernize is half the battle — the other half is choosing the right way to do it. Here are a few of the most common areas where modernization makes an immediate impact:
ERP Systems
ERP systems manage inventory, purchasing, scheduling, and financial operations. Because these systems sit at the center of manufacturing operations, replacing them can introduce significant risk, which is why modernization efforts often benefit from experienced infrastructure teams. Infrastructure modernization typically focuses on improving the servers and databases that support the ERP environment.
Manufacturing Execution Systems (MES) Platforms
Manufacturing Execution Systems coordinate real-time production processes and equipment monitoring. Infrastructure modernization can improve MES performance, reliability, and integration with other operational systems.
Production Databases
Manufacturing environments generate large volumes of operational data. Modernizing database infrastructure improves performance, scalability, and backup protection.
Engineering File Servers
Engineering teams often depend on centralized file servers storing CAD drawings and documentation. Modernizing storage infrastructure improves reliability and protects critical intellectual property.
Custom Internal Applications
Many manufacturers rely on internally developed software that supports production workflows. Instead of replacing these applications, modernization typically focuses on upgrading the infrastructure supporting them.
Choosing the Right Modernization Approach
Not all modernization strategies are the same. The right approach depends on your systems, risk tolerance, and long-term goals.
For most manufacturing environments, lift-and-shift or re-platforming hits the sweet spot between meaningful improvement and minimal disruption. In many cases, the right solution is a combination of these approaches, tailored to fit your specific systems and operational needs. Every environment is different, which is why it's helpful to talk through your options with an experienced infrastructure team.
The chart below compares common modernization approaches based on cost and potential level of disruption.
← Scroll to see full table →
| Approach | Description | Cost | Disruption |
|---|---|---|---|
| Lift-and-Shift to Cloud | Move workloads from physical servers to virtual/cloud infrastructure, with applications unchanged | Medium | Low |
| Re-platforming | Migrate applications to the cloud with small optimizations | Medium | Low |
| Re-architecting | Migrate to the cloud and completely redesign application architecture | High | High |
| Full Hardware Replacement | Replace physical server infrastructure entirely, keep applications the same | High | High |
Not sure which approach fits your environment? DataYard helps manufacturing teams assess their current infrastructure and choose the right path forward.
Let's Talk Shop →What Legacy System Modernization Actually Looks Like
In practice, modernization rarely involves replacing the applications themselves. Instead, it focuses on upgrading the surrounding infrastructure.
Typical modernization steps include:
- Migrating systems to virtualized environments
- Implementing private cloud infrastructure
- Integrating hybrid cloud capabilities
- Improving monitoring and security
- Strengthening backup and disaster recovery
This allows manufacturers to extend the life of stable applications while reducing infrastructure risk. One of the most effective tools in that modernization toolkit is hybrid cloud, and it is a particularly good fit for how manufacturers operate.
Why Hybrid Cloud Works Well for Manufacturers
A hybrid cloud combines private infrastructure with cloud services. According to the Flexera 2026 State of the Cloud Report, 73% of organizations now operate using a hybrid cloud strategy, combining private server infrastructure with other cloud services.
For manufacturing environments, this typically means:
- Legacy systems, domain controllers, or on-prem file servers operating in an on-prem server environment.
- Other cloud environments used for business-critical applications, scaling, and/or disaster recovery.
- Secure connectivity between facilities.
A Practical Modernization Roadmap
Most successful modernization projects follow a phased approach. Below are the four steps many companies take to modernize their systems.
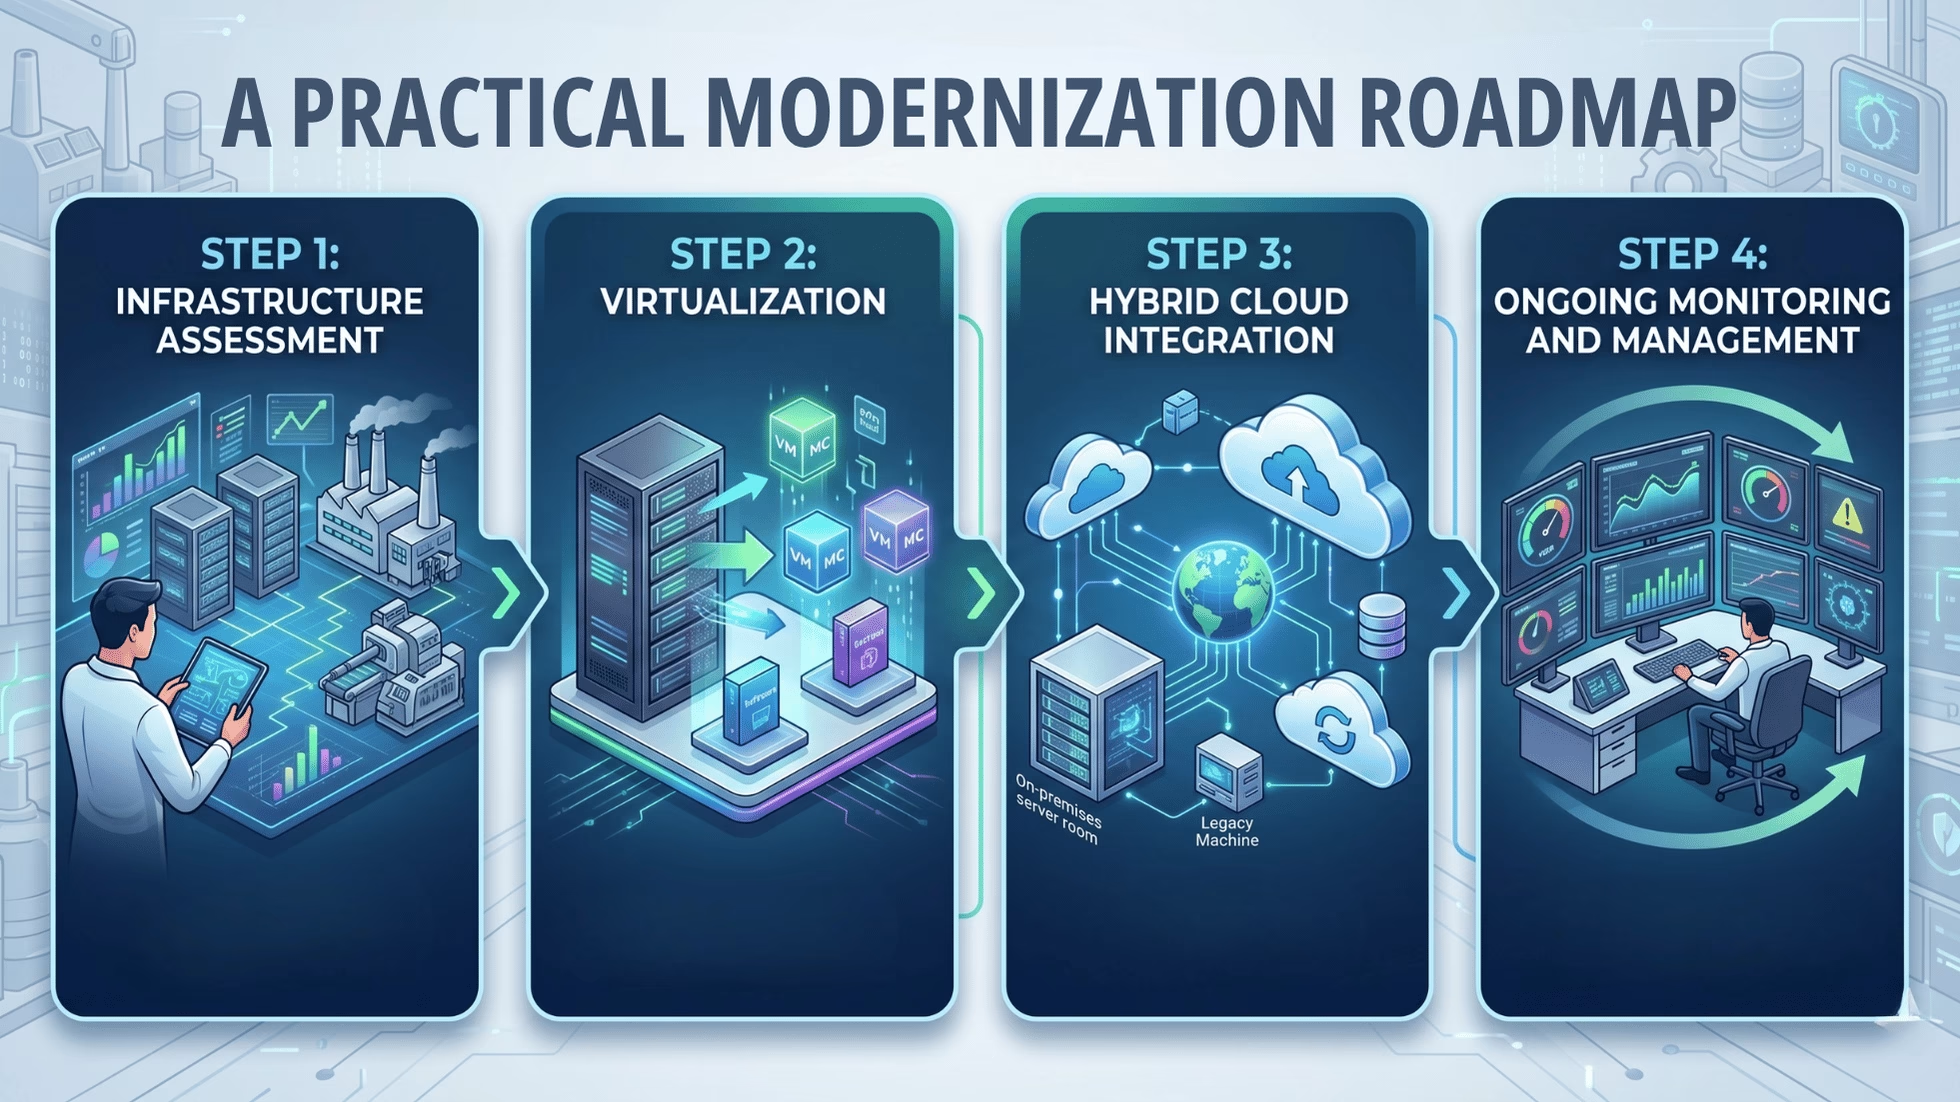
Below are the four steps many companies take to modernize their systems.
Infrastructure Assessment
Identify critical workloads, aging hardware, resource utilization, and operational dependencies.
Virtualization
Migrate systems from aging physical hardware to virtual infrastructure.
Hybrid Cloud Integration
Maintain a small physical server footprint on-prem to support legacy systems or domain services, but rely on cloud resources for business-critical apps, scalability, disaster recovery, and off-site backups.
Ongoing Monitoring and Management
Modern infrastructure requires continuous monitoring, patching, and proactive security management.
The Business Benefits of Modernizing Infrastructure
Modernizing legacy infrastructure delivers measurable benefits and is often the most practical path forward for manufacturing environments.
Modernization benefits include:
- Improved system reliability
- Reduced downtime risk
- Stronger cybersecurity protections
- Improved scalability and growth potential
- More predictable infrastructure costs
Most importantly, modernization via virtualization allows manufacturers to improve their IT environment without major disruption to production systems.
Choosing the Right Partner to Modernize Legacy Systems
Legacy system modernization doesn't have to mean replacing the systems that keep your business running. With the right infrastructure strategy, manufacturers can modernize around existing applications while improving reliability, security, and scalability. DataYard works with manufacturers to modernize infrastructure using virtualization, private cloud, and hybrid cloud environments designed to support critical production systems while minimizing operational disruption.
What to Look for in a Modernization Partner
Manufacturers evaluating infrastructure providers should prioritize:
Experience with Manufacturing Environments
Industrial systems often require custom networking and multi-site connectivity.
Reliability and Uptime
Infrastructure supporting production must prioritize stability and availability.
Security
Modern environments should include:
- Network segmentation
- Continuous monitoring
- Automated patching
- Secure backups
- Disaster recovery plans
Responsive Support
Manufacturers typically operate with lean IT teams and can benefit from providers offering direct engineering support.
Let's Figure It Out Together
Choose the right partner, and the results speak for themselves. DataYard checks all of those boxes. If you're ready to evaluate your infrastructure and start building a path forward, our team is ready to help.
The 3-2-1 Backup Strategy: What It Is and Where It Breaks Down
Three copies, two media types, one offsite. The 3-2-1 backup
Layered Security: Why Patching Alone Is Not Enough
Patching matters. It also cannot be the whole strategy. Here
Data Center Power Redundancy: How DataYard’s Dayton Facility Is Built
Data center power redundancy is about more than just backup